Posts by:

Tim Booher

Burning Weeds

Burning weeds is fun. It may also be cost effective, easy to apply than chemicals and just feels more natural. My neighbor once described a brief pass over weeds as “instant drought”. Maybe, but it works well. That is, unless your burner stops working.

The burner hooks directly to a propane gas tank. You just need a regulator, a flow value, and a wand. Light a spark and you have a nice torch.

In my case, I couldn’t get any gas to flow. I messed around trying to dissemble everything and then used compressed air to clear any blockages. This didn’t work. I started looking at new wands. They were > 100$ and repairing this was worth trying, but I needed to understand how this tool worked.

The key insight is that there is a small hole where the gas escapes. Mine was clogged. I put WD-40 on both sides of this hole and used a steel brush on my drill to clean this out and then compressed air until the blockage cleared. Next time, I won’t leave this wand out in the rain. Lesson learned.
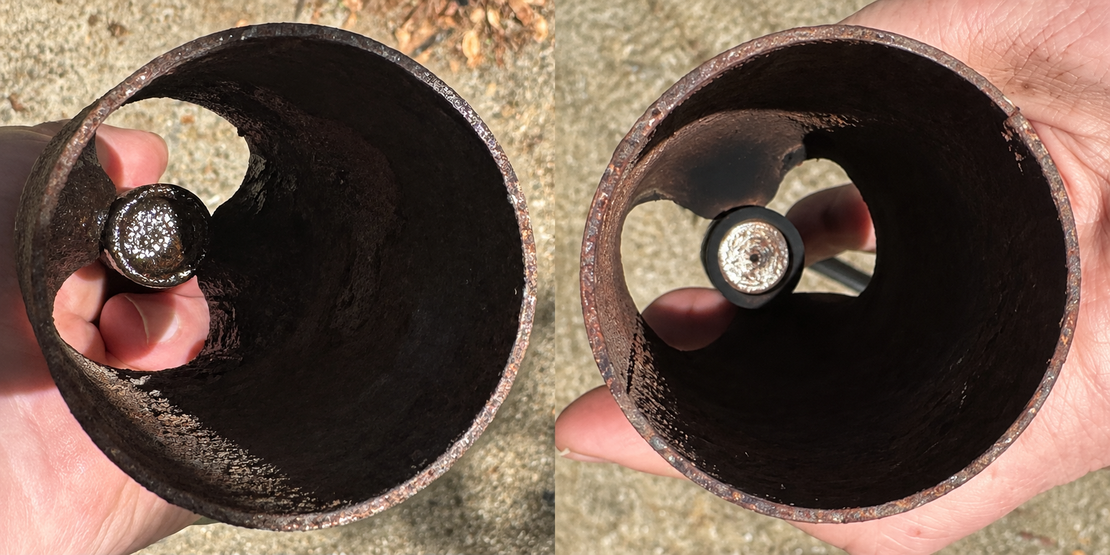
Fig 1. Before and after cleaning

The regulator is wrist-watch cool, it’s a mechanical feedback loop

The first part to understand is the regulator. In a typical direct-operated reducing regulator, outlet pressure pushes on a flexible diaphragm while a spring supplies the opposing force. A linkage connects that diaphragm to a valve at a restricted passage. The valve changes the opening through which higher-pressure gas enters the lower-pressure side.

Open the torch’s control valve and gas leaves the downstream side. As outlet pressure falls, its force on the diaphragm falls; spring force moves the mechanism toward a larger opening. When demand decreases, outlet pressure rises and the mechanism throttles toward closed. At a steady demand, it settles near a balance. The regulator responds continuously; it is not a pump or simply an on/off switch.
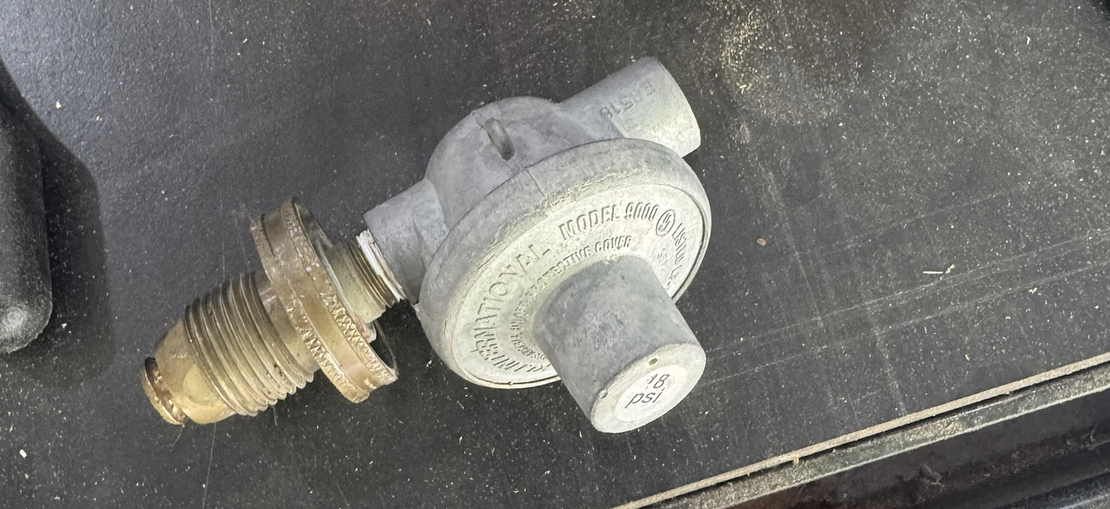
Image 1 – You always see this thing, but what does it do?

I can’t follow paragraphs like this, so I built an illustration. Watch the linked diaphragm, stem and valve move together while the spring length changes. Motion is exaggerated to explain the feedback direction; this is not a pressure-response calculation.

Illustration 1 – Regulator

A small fuel outlet inside a much larger cup

Flame Engineering describes a fitting welded to the pipe end with a pin-sized central orifice. This detail was critical to fix this. There is much power in building a 3d model of a part. You can explore exactly how things work and then do a very surgical fix. Professionals gain this knowledge over years in apprenticeships, but weekend hacks like me can get the same wisdom from a model.

First, pressure drives gas through the restricted outlet. The emerging jet transfers momentum to surrounding air, drawing air into the mixing region. Fuel and oxygen then burn, producing a nice focused torch. The large air openings and the small fuel opening perform different jobs.

Illustration 2 – Watch fuel draw air into the burner, mix and form a flame. Use Pause and Speed to explore the flow.

The end of the wand is a mixing chamber, not a safety shield. The torch turns a narrow stream of propane into a broad flow of heat as it mixes in this tube. Pressurized fuel travels down the wand and accelerates through a small outlet into the burner bell, which is 2 inches (about 51 mm) across on the Weed Dragon VT2-23C. The fast-moving jet pulls surrounding air through the openings behind the bell a process called entrainment. The wider tube gives that air and fuel room to mix as the jet spreads. Once ignited, the mixture releases heat, expands, and continues mixing with outside air beyond the mouth, producing a flame much wider than the original fuel jet. The bell helps shape this flow, but the flame’s width and length also depend on fuel flow, air supply, and wind. The drifting haze in the illustration makes normally invisible gas motion visible.

The heat does not necessarily peak at the burner’s face, and it does not simply fall as \(1/\text{distance}^2\). Near the torch, combustion, mixing, and the hot gas striking a surface all affect heat delivery. To understand the chemistry and the heat, let’s use NASA’s explanation of flame color. Blue in a real flame comes largely from light emitted by excited molecules during combustion. It is not a “cool” region. Yellow, orange, and red often come from glowing soot particles. Brightness and color alone cannot tell us the gas temperature or how much heat reaches a leaf.

The heat is not maximized at the end of the wand where fuel may still be mixing and burning. It takes distance for the reaction to increase. Farther downstream, the jet spreads, entrains cooler air, and loses speed and temperature. The concept here is heat flux:

qnet′′=h(Tgas−Tleaf)⏟heat carried by moving gas+qradiation, absorbed′′−qradiation, emitted′′⏟net radiant heatingq”_{\text{net}} = \underbrace{h(T_{\text{gas}}-T_{\text{leaf}})}_{\text{heat carried by moving gas}} + \underbrace{q”_{\text{radiation, absorbed}}-q”_{\text{radiation, emitted}}}_{\text{net radiant heating}}

Practically, this means you need to experiment on distance.
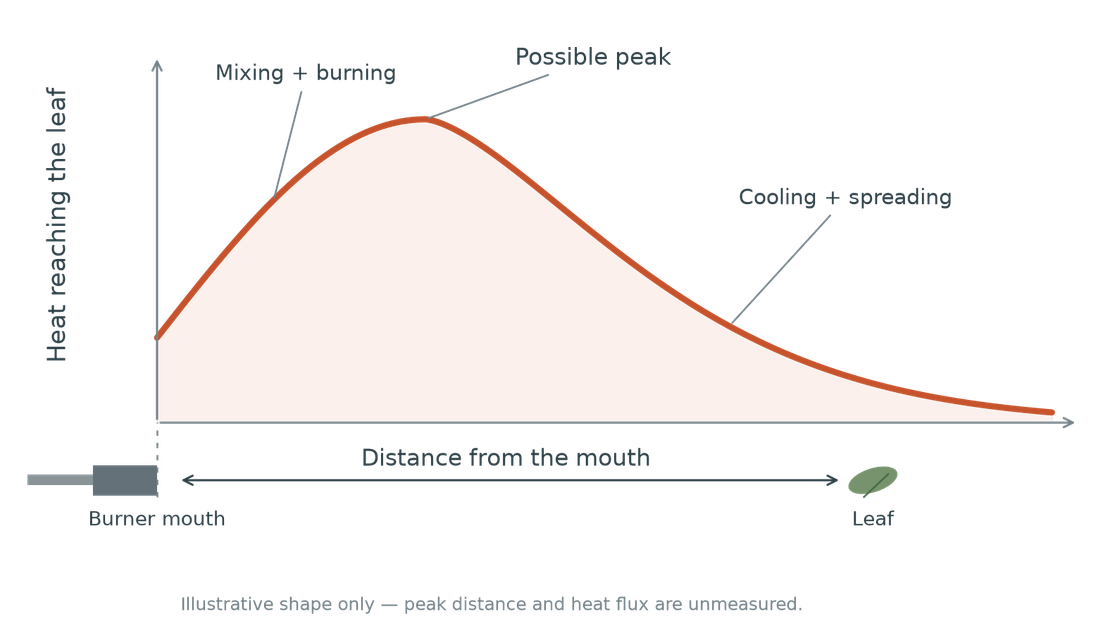
Image 2. Heat and distance from the wand

Why does a short pass of heat kill plants?

The trivial answer is that if you turn a plant into ash, it’s gone. That isn’t the idea here. I’ve learned a light pass that causes just a little wilt is best.

How does a pass of high heat kill a plant? A healthy leaf’s firmness depends partly on turgor: water pressure within living cells pressing against their walls. Membranes maintain the separation and chemical gradients that make normal cell function possible.

Illustration 3 – Watch heat damage the leaf’s cells, then follow its effects on the plant’s ability to recover.

The plant dies when damage exceeds its capacity to sustain itself and rebuild. Loss of support for the roots is part of that process, but damage to the growing points also matters.

Heat damages membranes and proteins, causing cells to lose function and water pressure. Leaves wilt and lose their ability to produce sugars that support the roots and new growth. The plant can recover if surviving leaves and stored reserves sustain it long enough for living buds to produce replacements. If that recovery fails, or heat destroys the growing points needed for replacement, the damage becomes fatal.
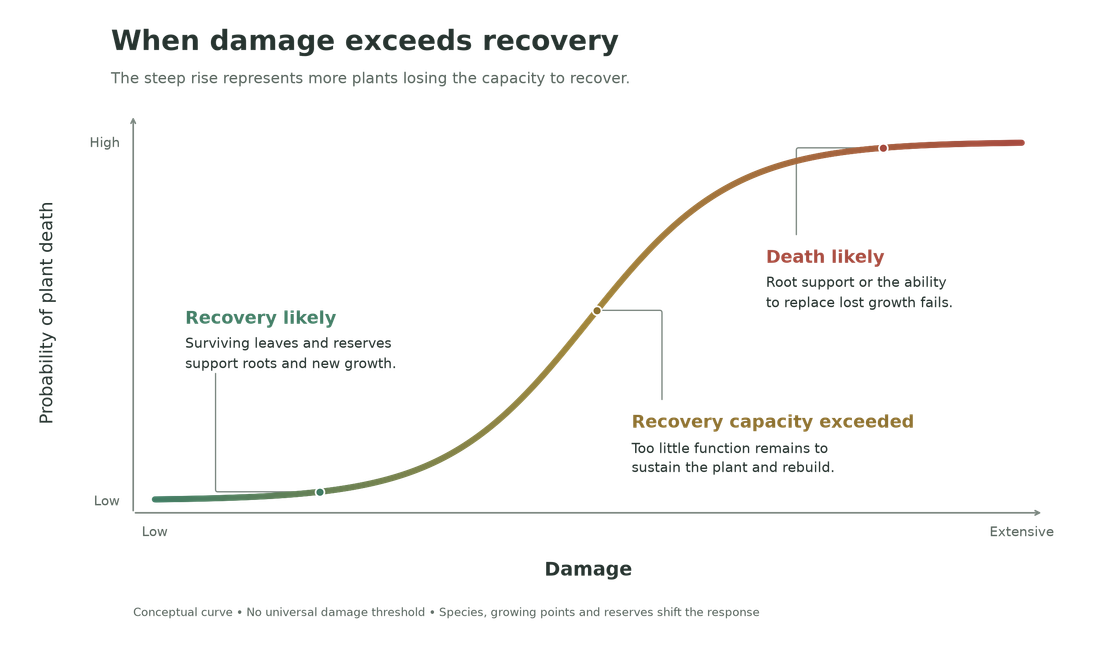
Image 4 – When the plant dies

The S-curve describes how increasing heat exposure pushes more plants beyond that recovery limit. At low doses, most recover. Through the steep middle, more sustain fatal damage. At high doses, most susceptible plants have already crossed the limit. There is no universal percentage of leaf loss that kills every plant; protected buds and stored reserves change the outcome. Also, a curve measuring reduced growth must not be mistaken for a curve measuring death.

To do it right, pass the heat across the foliage and exposed growing points, the tips or buds producing new leaves. Burning through the stem could work if you really destroy it but that takes too much time.

From my reading on this, a good field check is to let the treated leaf cool, then gently press it between thumb and finger. A lasting thumbprint, dark watery appearance, or easily crushed tissue indicates sufficient heat injury in that area.

Why the same treatment can kill one weed and spare another

Burning doesn’t affect all plants equally. Small broadleaf seedlings are often susceptible because their growing points are exposed. Grasses can protect those growing points near the soil or within leaf sheaths. Established perennials can retain roots, crowns or underground stems that produce another shoot after the visible foliage is injured. A wilted top is not proof of a dead root system. [9] [11]

Nebraska experiments found that response changed with propane dose, species, growth stage and time of day; grasses generally tolerated more flaming than broadleaf species. So a universal pass speed or a single exposure will not kill every weed. [10]

Flaming also has practical limits. It is nonselective, can injure desirable plants, and can ignite dry vegetation or mulch. (Ask my wife about lighting the house on fire.) [9]

The useful question is not “How completely did I burn it?” It is whether enough vulnerable living tissue was injured to prevent recovery, and whether protected growing points can still restart growth. Several fast passes are a good experimental way to find out.

Sources & model notes

  1. Flame Engineering: 18 psi high-pressure regulator
  2. Flame Engineering: Weed Dragon specifications
  3. Emerson: Self-operated regulators
  4. Emerson: Direct-operated regulator force balance
  5. Flame Engineering: Orifice identification FAQ
  6. US patent 3357474: Related historical burner; not this model’s internal drawing
  7. University of Nebraska–Lincoln: Flame-weeding research
  8. Nebraska CropWatch: Thermal injury mechanisms
  9. Iowa State University: Flame weeding and plant response
  10. Ulloa, University of Nebraska–Lincoln: Flaming response research dissertation
  11. University of Maryland Extension: Managing weeds without chemicals
  12. OpenStax Biology: Water transport and turgor
By One Comment

Handwiring the Future

A very cool new compiler trick may point to a much bigger idea: a new way to think about how programs and learning fit together. In fact, this may actually be a new way to think about computation itself. The core idea is that programs can be both specified and trained.

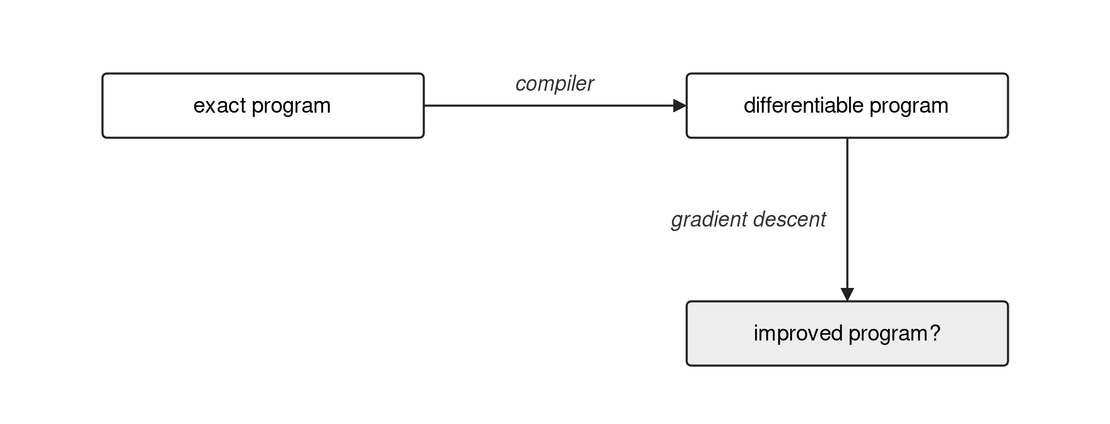
How? Cheng Lou released a project called Handwired that takes ordinary JavaScript (conditionals, loops, state) and transforms it into the kinds of mathematical operations we associate with neural networks. This turns a program you explicitly write into something that can potentially be improved using the same learning machinery behind modern AI. That means software no longer has to be only written or only learned, it can start as a precise program and then become trainable.

You could get code started and let the real world finish it for you, picking and choosing what bits stay fixed and what parts get better.

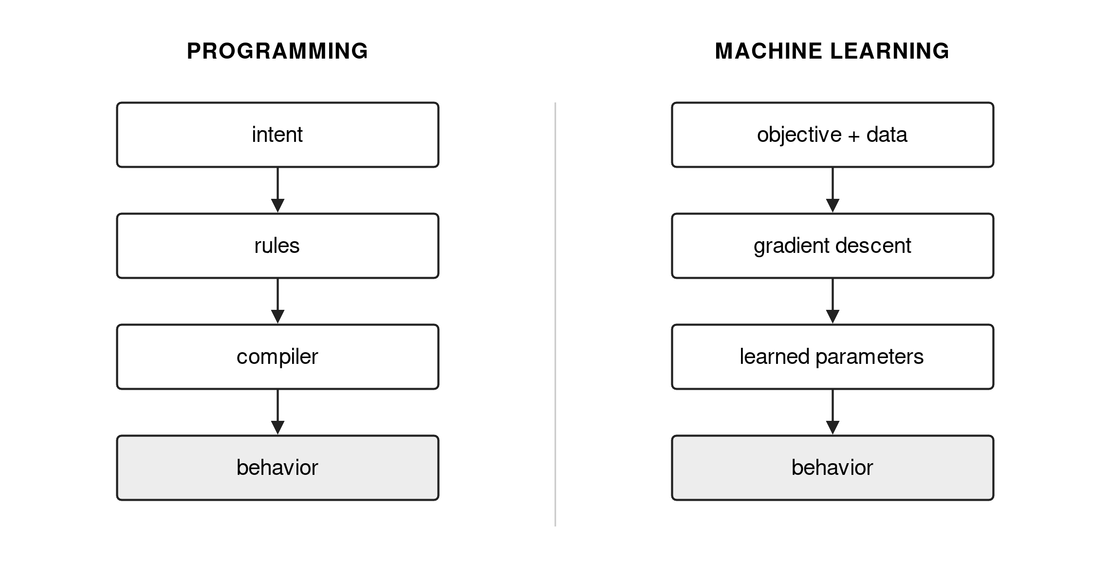
Ok, this probably makes no sense. Let’s break it down. We have traditionally had two ways to tell computers what we want: you tell the machine what to do step by step (programming), or you show it examples and let it learn the behavior for itself (machine learning). Let’s explore these to show exactly what is new here.

For most of computing history, if you wanted a computer to do something, you wrote a program. You wrote:

if this happens:
    do this
else:
    do that

The great virtue of software is precision. A compiler takes your intent and progressively lowers it into another representation while trying very hard to preserve its semantics.

Machine learning approaches the problem from almost the opposite direction. Instead of specifying the mechanism and getting the behavior, we specify the behavior we want (through data, examples, and an objective) and let optimization discover the mechanism. With a neural network, we generally don’t know the program. We define an architecture, provide examples or an objective, initialize a huge set of parameters, calculate an error, and use gradient descent to modify those parameters until useful behavior emerges.

Programming gives us control. Machine learning gives us adaptability. What if we could have both?

Handwired starts with a program, not a training set or model that learns an approximation of the behavior. Take:

if a > 4:
    return 10
else:
    return 12

Handwired can transform this kind of control flow into arithmetic constructed from ReLU1 operations and weighted values. Those operations can then be collected into the matrix-oriented representation used by neural networks.

So we get something like:

The question mark is important. We can’t assume that gradient descent magically improves any software, but the question can fundamentally change: Can I compile the program I already know into a representation that learning can subsequently modify?

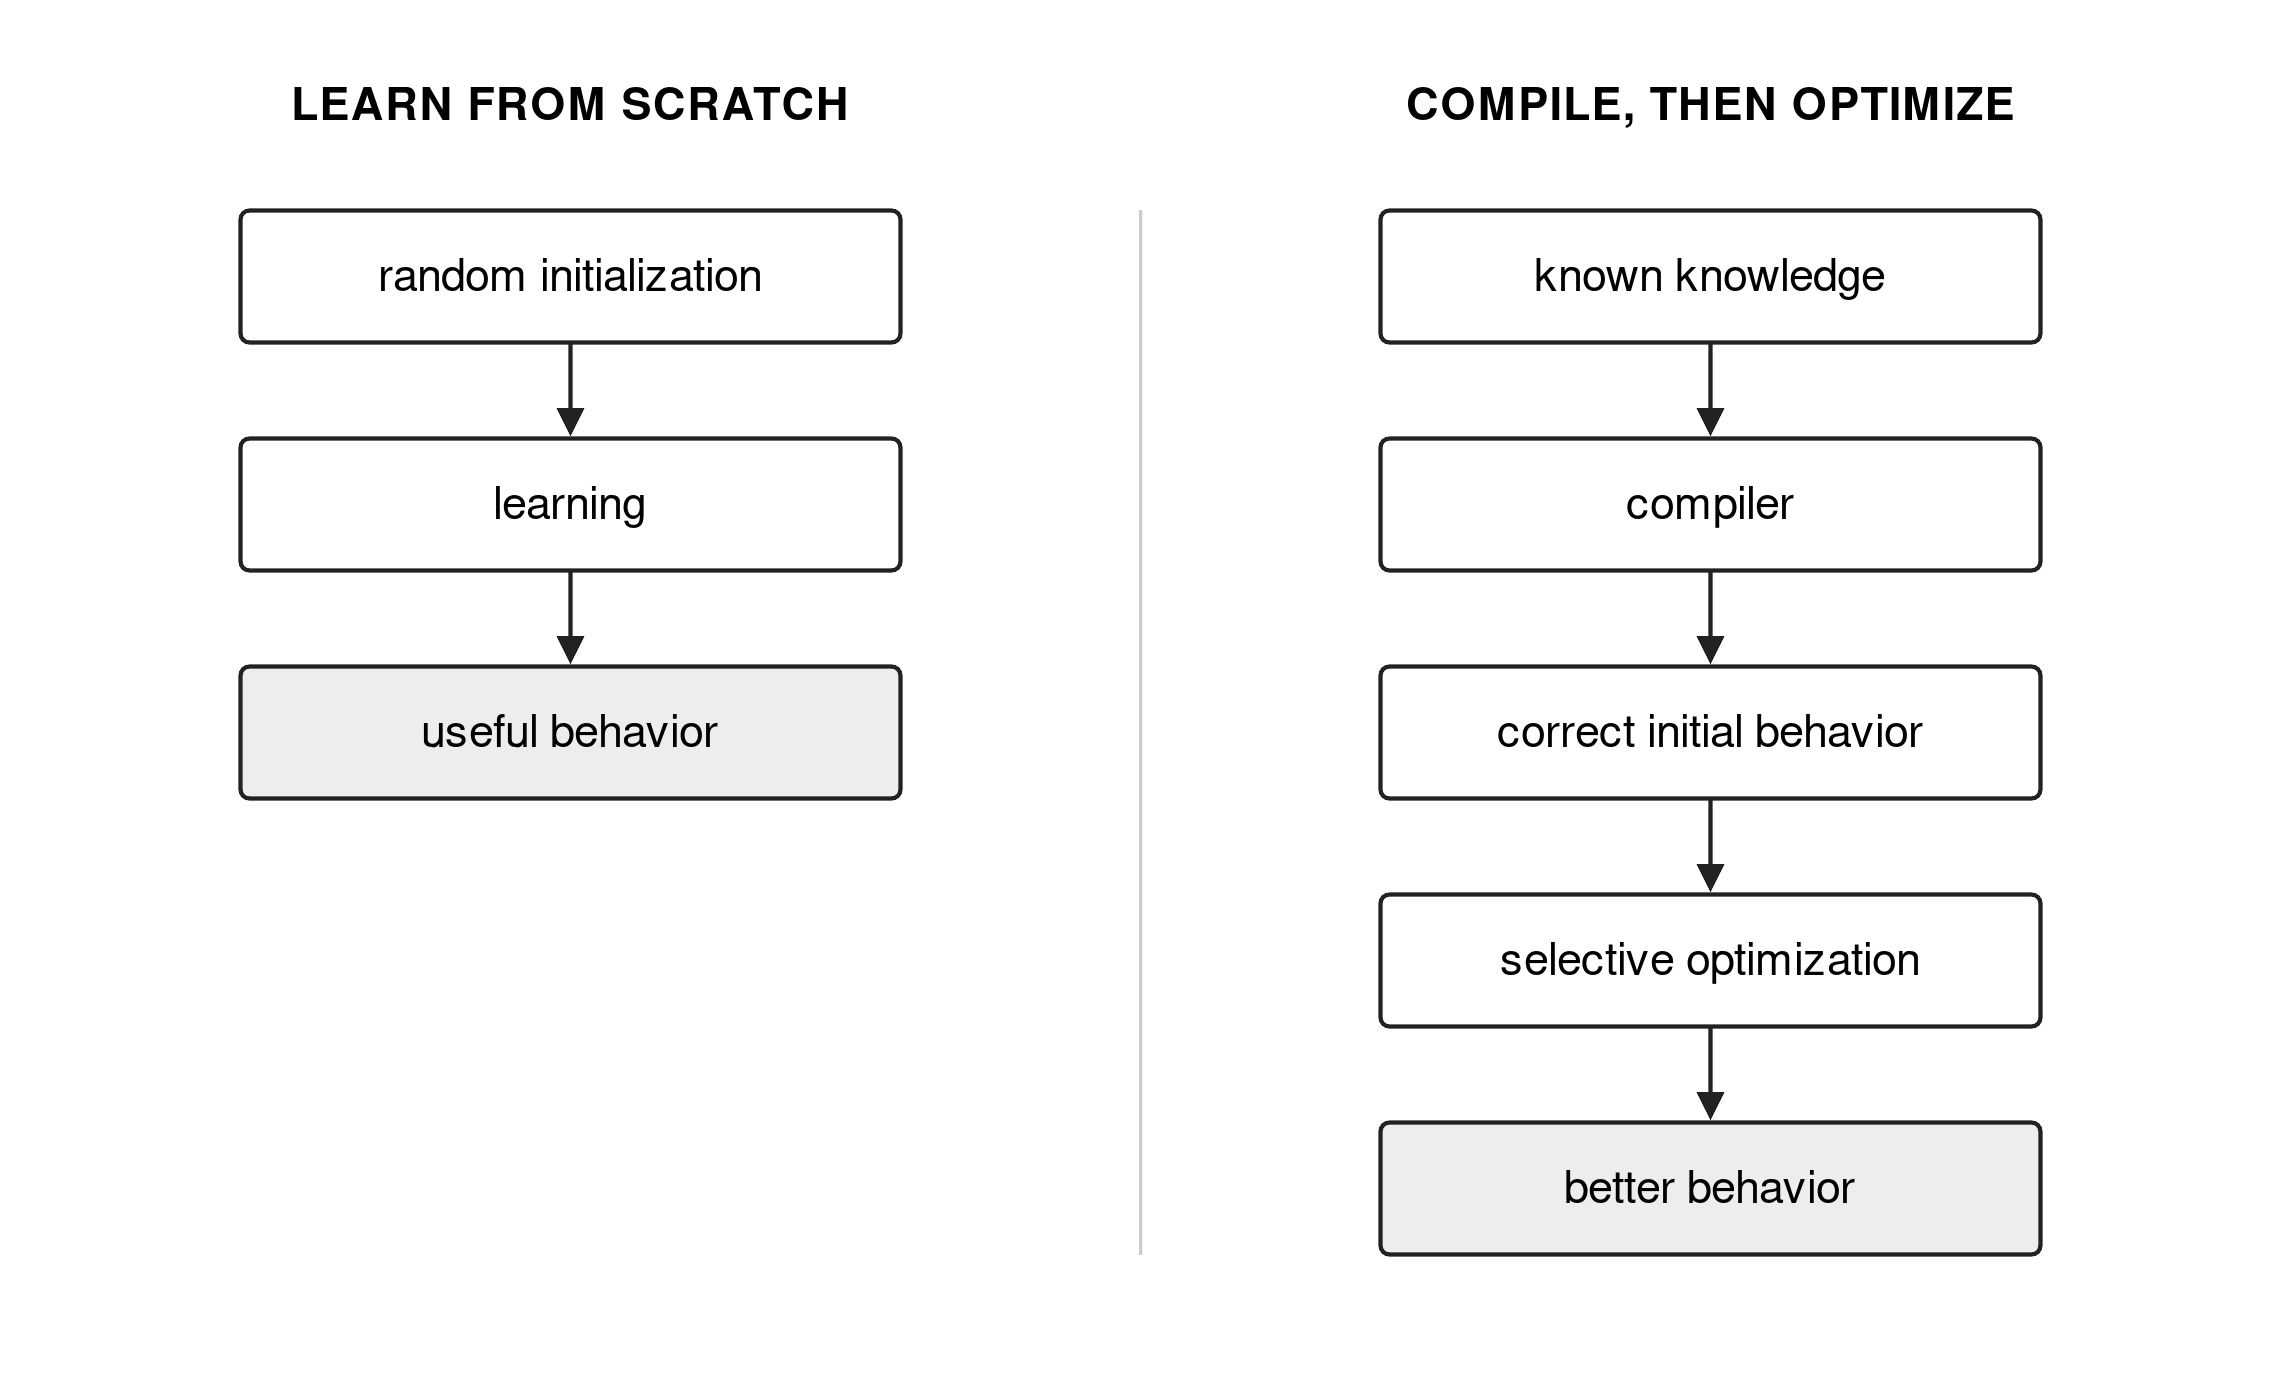
I can’t tell if this has more potential to change programming or machine learning. Modern neural networks generally begin ignorant and get smarter with better data. But imagine reversing that. Suppose we start with a system that already contains substantial amounts of human knowledge: physical laws, constraints, safety rules, existing software, engineering tools, etc.

Those things don’t have to be rediscovered through training, they can be compiled in. We can then make only the places where uncertainty or optimization actually exists learnable.

Instead of data driving the system performance, you can encode what you know about the world.

Learning becomes a refinement mechanism instead of the mechanism by which the entire system comes into existence.

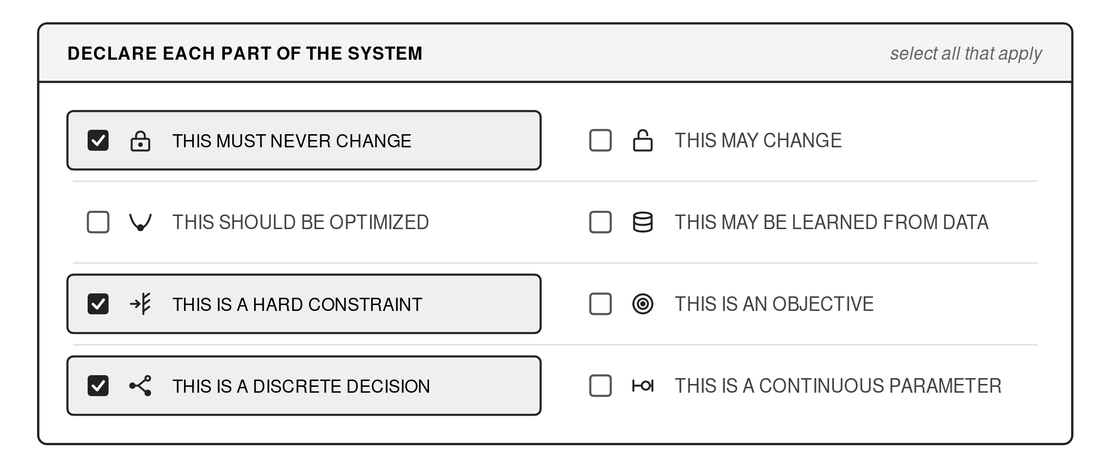
This might eventually give us a very different way to build software. Imagine writing systems in which the compiler understands that different portions have different semantics with different options.

Now the compiler isn’t merely generating executable code. It is generating an optimization space. Some of the resulting representation is frozen. Some of it is trainable. Some is governed by constraints.

The boundary between “program” and “model” becomes much less rigid.

I thought about how to make this more clear interactively. Suppose we want a function that turns 0 into 1, 1 into 3, and 2 into 5, continuing the same pattern. Choose an input above and watch it travel through the box. The answer is already specified; the question mark is there because we haven’t said how the machine will produce it.

Change different input values below to set the stage for how this more complicated idea works.

Input

Choose a number.

This distinction is the starting point. A task describes the behavior we want: for a given input, what should the output be? The example above doesn’t yet tell us how to build that behavior. Most of us would go into SAT math problem mode and see that there is a linear equation that you can pull out of this and we would do the algebra and get:

f(x)=2x+1f(x) = 2\,x+1

But what if we just fed a bunch of examples to a machine learning system? It’s just another way to get a functional system. To get some intuition for this, let’s extend this basic example. Click “learn” below to see a cartoon of how a system arrives at the same capability through these two different ideas.

Input

Programming

3 → 7

Machine learning

3 → 1.50

● Prediction○ Target

Training error4.25

That is pretty basic description of the difference between a program and a machine learning model, but it sets the stage to get what is going on with Handwired.

Here we take a working program and give it a few adjustable knobs. Handwired does this by translating the program’s rules into the arithmetic of a neural network, with weights chosen to reproduce its behavior from the start.

To get this, consider a trivial program. If the input is greater than 4, return 10; otherwise, return 12. Compilation preserves those answers. But! What if we wanted to adjust this? We could re-compile a new one, or we can “unlock” one weight and introduce examples asking for 8 instead of 10.

Watch the blue dots move toward their targets as learning adjusts that answer, while the decision and the other answer stay fixed. The program supplies the starting knowledge; learning refines the part we allow to change.

Try different input values and then click “compile” below, followed by “learn” to watch the system adapt.

Input
x > 4 ? 10 : 12Written rule

A decision picks one of two answers.

● Output○ Target

Inside the gateg = max(0, x − 4) − max(0, x − 5)

For these whole-number inputs, g is 0 or 1. The compiled output is g × 10 + (1 − g) × 12.

This illustration follows Handwired’s published arithmetic. It is a small explanatory model, not the Handwired compiler itself.

Input 5 produces 10.

So with some understanding of this. What could this actually do?

First, this capability could give us a very different way to make ordinary code run faster. Handwired takes control flow that looks sequential, loops, conditionals, state, and lowers it into a small vocabulary of fast math operations. GPUs and modern ML infrastructure are extraordinarily good at executing and optimizing exactly those kinds of operations. Cheng Lou's JSON-search demo, for example, takes traditionally written JavaScript and runs the resulting computation over 100,000 documents on WebGPU in milliseconds. He also points out that once the program has been reduced to these primitives, techniques such as fusion, sparsity, and reordering become available to the compiler. This does not mean arbitrary JavaScript suddenly becomes faster on a GPU, but it raises an intriguing possibility: can we write code in a familiar sequential way and let the compiler discover a massively parallel way to execute it.

Second, a differentiable program gives us a new way to ask questions and gain deeper understanding about what the program is doing. Traditional debugging can tell us how a value flowed through a program; differentiation can potentially tell us how sensitive the final result is to values and parameters throughout that computation. In other words, instead of merely asking, “Why did I get this output?” we can sometimes ask, “Which things would most change this output, and in which direction?” This is already the basic power of automatic differentiation systems such as JAX: grad transforms a function into another function that calculates its gradient, while reverse-mode differentiation propagates information backward through a computation. Handwired's contribution is interesting because it tries to bring ordinary program structures into that same differentiable world. This isn't human-like understanding of code, but it could give software something extremely useful: a map of its own sensitivities.

Third, once you have those gradients, parts of the program can potentially optimize themselves. This is where the idea moves beyond an unusual execution strategy. Handwired's weights are initially produced by the compiler rather than learned, so the network begins by implementing the program that was written. But Cheng explicitly proposes unfreezing those compiler-created weights and training them. One of the project's demos already does this: its “Learned Gallery” compiles a photo-layout program, exposes adjustable weights, defines a loss based on the desired layout, and updates those weights live until the result better matches what the user drew. The important conceptual shift is that optimization does not have to start from random parameters and somehow rediscover the program. It can start from the program we already know and improve from there.

Fourth, this makes it possible for software to adapt differently to different people. Imagine that the fundamental rules of an application remain frozen, but particular parameters (layout, thresholds, ranking behavior, defaults, perhaps even pieces of a workflow) are allowed to adapt against an objective derived from how an individual uses it. Handwired does not yet demonstrate a general-purpose self-personalizing application, so this part is a direction rather than a result. But the mechanism is visible: the Learned Gallery changes its parameters in response to a user's desired layout, and Cheng explicitly suggests attaching a specific frozen program to a generic neural network and training the combined system end-to-end. That suggests an interesting alternative to today's personalization systems: instead of putting an AI model beside the application, parts of the application itself could become trainable while the rest remains fixed.

Finally, the biggest implication may be a new way of deciding what software actually is. We have traditionally separated programs, where humans specify behavior, from machine-learning models, where optimization discovers behavior. Handwired suggests a middle ground. A future program might contain things that are immutable, things that are differentiable, things that can be optimized, and things that can be learned from data, all inside the same computational object. Other systems such as JAX already show how compilation, vectorization, and differentiation can be composed as transformations of programs; Handwired makes the provocative move of starting with familiar imperative program structures and compiling them into that world. The result points toward software where we can specify what we know, preserve what must remain true, and optimize what we are willing to change.

These are really incredible days to be a builder. I hope this helped make some recent research accessible.

  1. A ReLU is just a very simple mathematical function:
    \( \text{ReLU}(x)=\max(0,x) \) ReLUs are useful because they are extremely simple, fast, and add the nonlinearity neural networks need to learn complex patterns. They also preserve useful gradients for positive inputs, which makes deep networks much easier to train. ↩︎
By 0 Comments

Garage Door Simulator

My son had a physics assignment to estimate the power required to raise a garage door. He needed to make a video for this. I wanted to build an interactive simulation to teach about a simplified linearized model versus what differential equations can actually do in the real world.

Now that I’m using AI to understand the world around me, my son’s physics project provided an opportunity to understand how garage doors work. They’re super simple, just a motor that pulls on a door. But there’s a couple interesting things going on. The first one is that it’s possible when you disconnect the motor to just lift the several hundred pounds of door up with a single arm because the torsion spring is pulling it up. And the door starts to move horizontally after the door goes around the first turn, which gets it out of the way but also makes it easier to move.

Illustration 1 – Drag the slider to lift the case off, then run the motor and watch the worm, gear, sprocket and chain open the door.

The motor itself in my garage runs on 120 volt AC and spins really fast. It started and stopped by a start-run capacitor. Newer units use a DC motor feed from a transformer and rectifier to allow soft start and battery backup.

Inside the opener’s AC motor there are two separate coils of wire wound around the stationary outer part, the stator. Each coil becomes an electromagnet when current flows through it.

Illustration 2 – The rotor always chases the field from the coil that peaks first toward the one that peaks second. Drag the slider to watch it, then switch the capacitor to the other coil and the rotor runs backward.

The capacitor matters because household AC power alone is a simple sine wave that would just make the motor buzz back and forth, not turn. The capacitor delays the current into one of the coils by a fraction of a cycle. So the two coils peak one after the other instead of together. Let’s name the coils Coil A and Coil B. That handoff between the coils makes the magnetic field sweep around the motor, and the rotor follows it. This is just like two hands spinning a wheel one after the other.

To reverse the garage door, switch the order of the capacitor firing: the capacitor on coil A and A lags, so the field sweeps one way. Put it on coil B and B lags, so it sweeps the other way. In many openers the two coils are identical, and the capacitor is wired between them. The “up” relay feeds power to one end and the “down” relay to the other, which decides which coil gets the delayed current.

Since the motor spins at about 1,500 RPM, a worm on the motor shaft drives a larger worm gear, which is often made out of nylon, which reduces from 10 to 40 to 1. A worm drive is good because it’s hard to back drive, which helps hold the door in place when the motor stops. This worm gear turns the output shaft, and the sprocket on that shaft pulls the chain. A pretty simple drivetrain.

Illustration 3 – Drag the slider to open the door. Drag the model to turn it, or tap Close-up to see the forces at the door arm.

The arrows in the illustration show the forces on the door at each point in its travel. The red arrow is gravity: the door’s 78 kg pulls down with about 765 N from its centre of mass. Gravity matters less as the door goes more horizontal. The magenta arrows are the lift from the torsion springs, delivered through the two cables. With the door closed they carry almost the whole 765 N, about 380 N per cable. As the door rolls onto the horizontal track, the track takes over more of its weight and the magenta arrows shrink to match. Because the springs balance the door, the opener only has to make up the difference. The dark cyan arrow is the opener’s force on the door, pushed through the door arm. At the start of opening it is only about 20 N, just enough to overcome roller friction and the drag of the bottom seal. The light cyan arrows split that force into a lift and a pull.

With the door closed the arm leans about 42° from vertical, so it pulls up and back at once, and the arm carries about one and a half times the chain’s pull. The springs do the heavy lifting; the motor steers and tops up.

The torsion spring is cool because it is not a normal spring with a linear constant that increases its force. It doesn’t pull on anything directly; it twists. One end is bolted to a bracket on the wall and cannot turn. The other end is clamped to the steel shaft that runs above the door. When the door is closed, the spring has been wound about seven turns.

Illustration 4 – Drag the slider to open the door. The wound spring twists the shaft, the drum reels in the cable, and the cable lifts the door. Watch the coils loosen as the spring gives up its twist.

Like a wound-up rubber band it is always trying to unwind, and the only part free to move is the shaft. So the spring twists the shaft, about 19 newton-metres from each spring in this example. At each end of the shaft is a small drum, about 10 cm across, with a steel cable wrapped around it and running down to the bottom corner of the door. As the shaft tries to turn, the drums try to reel those cables in. A twist of 19 N·m on a drum with a 5 cm radius becomes a pull of about 380 N on each cable, and two cables together roughly equal the door’s own weight (78 kg, or about 765 N).

The door is effectively hanging from a pair of wound-up springs, balanced. As the door rises, the cables wind onto the drums and the springs give up their twist. They lift less and less, which is fine, because the horizontal track is taking over more and more of the door’s weight. What a cool, balanced, system.

You can see a full simulation of all the forces at garagedoor.theboohers.org/ but you can get a small sample of everything together below. (Btw, perfect introduction to differential equations.)

Illustration 5 – Drag the door or press Open & close. Change the spring, door mass and friction to see how the forces and power change.

The Math

This is a great chance to show differential equations in action. The model has a single coordinate, \( s \): how far the bottom roller has travelled along the track. Every other position follows from it.

The whole door has one moving part as far as the math is concerned: \(s\), how far the bottom roller has travelled along the track. Every section, roller, cable and the trolley can be worked out from \(s\), so one equation describes the entire door.

In words: the force needed to speed the door up equals what the opener supplies, minus gravity, plus the spring, minus friction.

M(s)s¨+12M′(s)s˙2=Fop−G(s)+S(s)−Ffsgn⁡(s˙)\begin{aligned} M(s)\,\ddot s + \tfrac12 M'(s)\,\dot s^{2} &= F_{\text{op}} \\ &\quad – G(s) \\ &\quad + S(s) \\ &\quad – F_f\,\operatorname{sgn}(\dot s) \end{aligned}

The left side is the door’s inertia: \(M(s)\) is how heavy the door feels at position \(s\), \(\ddot s\) is its acceleration and \(\dot s\) its speed. On the right, \(F_{\text{op}}\) is the opener’s push, \(G\) is gravity, \(S\) is the spring’s lift and \(F_f\) is friction, which always opposes the motion. The simulation runs this equation backward: it knows how the door moves and solves for \(F_{\text{op}}\), the force the opener must supply at each point.

The door’s effective mass adds up every section’s sliding and turning:

M(s)=∑i=14ms‖d𝐜ids‖2+∑i=14msh212(dϕids)2\begin{aligned} M(s) &= \sum_{i=1}^{4} m_s \left\lVert \frac{d\mathbf c_i}{ds} \right\rVert^{2} \\ &\quad + \sum_{i=1}^{4} \frac{m_s h^{2}}{12} \left( \frac{d\phi_i}{ds} \right)^{2} \end{aligned}

Each of the four sections has mass \(m_s\) and height \(h\). The first sum is the sections sliding, with \(\mathbf c_i\) the centre of section \(i\). The second is the sections turning, with \(\phi_i\) its tilt and \(m_s h^{2}/12\) a flat panel’s resistance to rotating. Because the sections speed up and tilt as they round the curve, \(M(s)\) changes along the track, and that is where the \(\tfrac12 M'(s)\,\dot s^{2}\) term in the main equation comes from.

Gravity is the slope of the door’s potential energy:

Ug(s)=∑i=14msgy‾i(s)G(s)=dUgds\begin{aligned} U_g(s) &= \sum_{i=1}^{4} m_s\, g\, \bar y_i(s) \\ G(s) &= \frac{dU_g}{ds} \end{aligned}

\(\bar y_i\) is the height of each section’s centre. \(G\) is largest when the door is closed and hanging straight down, and falls toward zero as the sections lie flat on the horizontal track, where the track carries their weight.

The torsion spring unwinds as the cable winds onto the drum:

n(s)=n0−L0−L(s)2πrdTc(s)=kn(s)rdS(s)=−Tc(s)dLds\begin{aligned} n(s) &= n_0 – \frac{L_0 – L(s)}{2\pi r_d} \\ T_c(s) &= \frac{k\, n(s)}{r_d} \\ S(s) &= -\,T_c(s)\, \frac{dL}{ds} \end{aligned}

The springs start wound \(n_0\) turns, about 7 here. Every \(2\pi r_d\) of cable wound onto a drum of radius \(r_d\) gives back one turn, so \(n(s)\) is the wind left. The spring’s twist is \(k\) newton-metres per turn, and the drum turns it into the cable pull \(T_c\). \(S\) is that pull measured along the door’s travel. It is positive because the cable shortens as the door rises. A balanced spring makes \(S\) track \(G\) almost exactly.

Friction comes from the rollers pressing on the track:

Nj=wj|tz(rj)|+mjvj2RFf=μ∑jNj|drjds|+Fseal\begin{aligned} N_j &= w_j\,\lvert t_z(r_j) \rvert + \frac{m_j v_j^{2}}{R} \\ F_f &= \mu \sum_{j} N_j \left| \frac{dr_j}{ds} \right| + F_{\text{seal}} \end{aligned}

\(N_j\) is how hard roller \(j\) presses on the track. On the vertical track \(t_z = 0\) and the cables hold the door, so the rollers only guide it. On the horizontal track \(t_z = 1\) and the full weight share \(w_j\) rests on the roller. On the curve of radius \(R\), a moving roller is also pushed outward by \(m_j v_j^{2}/R\). Rolling friction is a small fraction \(\mu\) (about 0.03) of that, plus a steady drag \(F_{\text{seal}}\) from the bottom seal and hinges.

Finally, the opener and the electric bill:

Ftrolley=Fopζ′(s)P=Fops˙=FtrolleyvtPwall=Pstandby+max⁡(P,0)η\begin{aligned} F_{\text{trolley}} &= \frac{F_{\text{op}}}{\zeta'(s)} \\ P &= F_{\text{op}}\,\dot s = F_{\text{trolley}}\, v_t \\ P_{\text{wall}} &= P_{\text{standby}} + \frac{\max(P,\,0)}{\eta} \end{aligned}

The chain pulls a trolley, and the trolley pulls the door through the door arm. \(\zeta'(s)\) is how far the trolley moves per unit of door travel, so where the trolley moves less than the door, the chain must pull harder. Power is force times speed, the same at the door or at the trolley (moving at \(v_t\), about 0.18 m/s). The motor and gearbox are about 55% efficient (\(\eta\)), and the board and radio draw about 8 W on standby (\(P_{\text{standby}}\)). The \(\max(P,\,0)\) means that when the door pushes back on the motor, that energy is lost as heat rather than returned to the wall.

By 0 Comments

Understanding and Fixing my Gate

Texas introduced us to cowboy hats and electric gates, in our case a a Nice Apollo 1500LA. It’s a long-running linear actuator swing gate: simple enough to be something I can repair, but just complicated enough to be difficult. The whole gate is really two different parts: a 636 control board and a 816 actuator. In the past, I documented how I connected our gate to Alexa through a WiFi connection in Gate Automation. This post is about how our gate works and how to fix it.

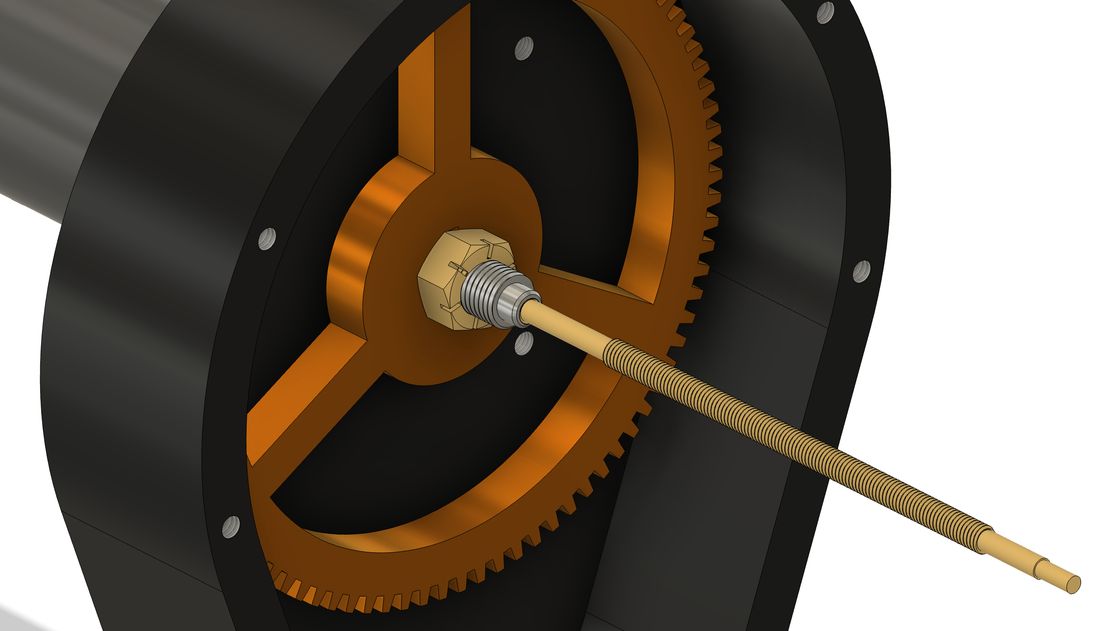
Our gate started opening past the limit switch and now I have to fix the 816 actuator, it’s a 12-volt DC motor that turns a pinon and spur gear which drives the central Acme lead screw. I had just fixed the broken spur gear and the old motor that lost much of its usable torque under load. After a couple of successful months after I replaced the motor and the spur gear, the limit screw broke and the gate only stopped at at absolute min extension. Slide below to see all these parts and how they work.

Illustration 1 – Drag the slider to open the housing and run the gears.

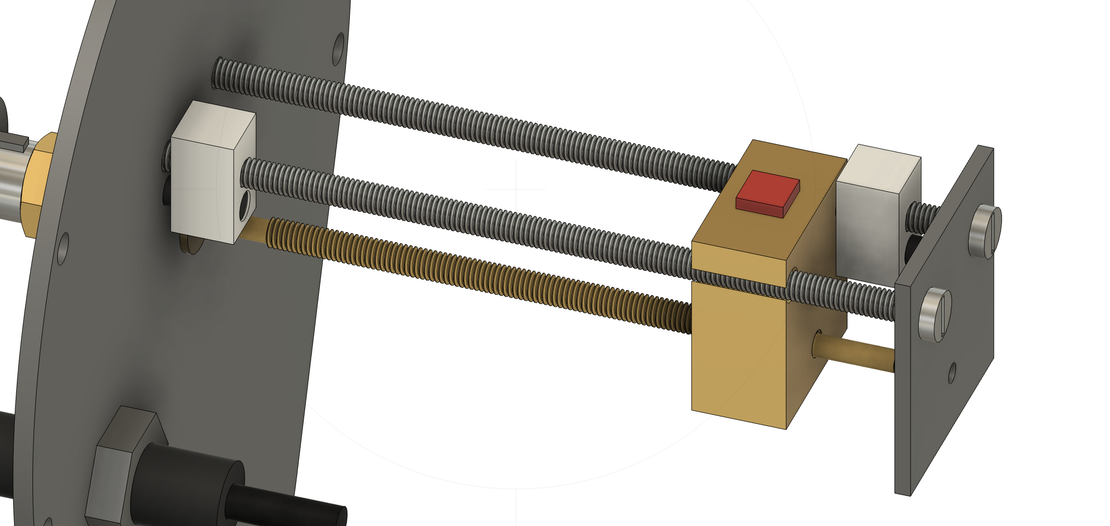
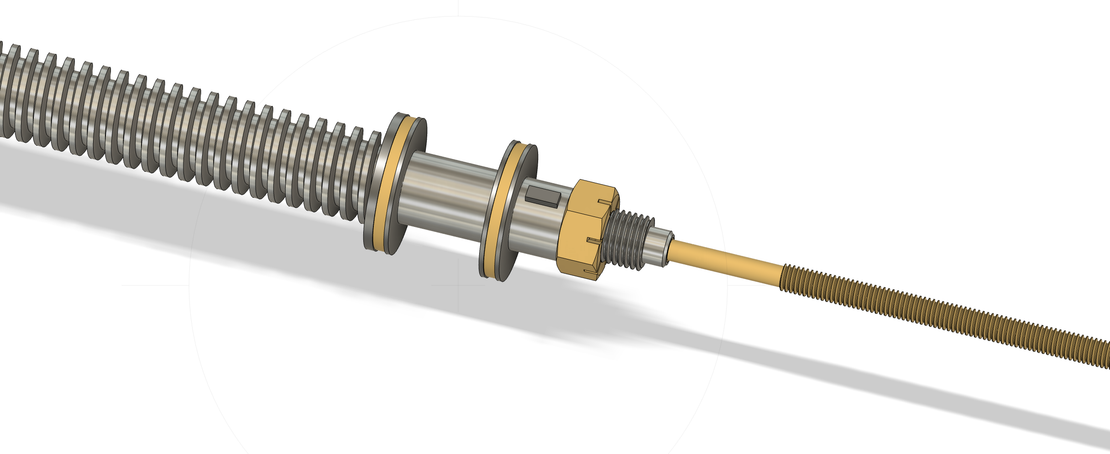
I opened up the housing to find that the A2019 limit screwwas broken and the key was broken as well. The A2019 limit screw threads directly the end of theACME lead screw so they move together. The illustration below shows how this works. A travellercarrying amagnetrides on the limit screw‘s thread. Two guide bolts keep the magnet from turning.

Illustration 2 – The traveller walks along the A2019 limit screw until a switch trips.

As the arm extends or retracts, the traveller walks slowly along the tower. Its position mirrors the gate. At each end of its travel sits a proximity switch on a limit block. When the magnet reaches a switch, the switch trips and tells the control board to stop the motor, one switch for fully open and one for fully closed.

Fig 1 – The traveler uses the guide bolts to stay vertical

So how does a magnet generate a signal to the controller board? A magnet induces an electric field. As the magnet approaches, the field strength \(B\) at the switch climbs steeply, roughly as \(1/d^3\), but continuously. My guess is that the gate has a Hall-effect sensor where current through a thin semiconductor is pushed sideways by the field, producing a tiny voltage proportional to \(B\). On its own that’s still analogue. An on-chip Schmitt trigger (a comparator with two thresholds, on above one and off below a lower one) flips its output transistor fully on or off.

Another interesting thing: the lead screw moves about 5 tpi (threads per inch) or 0.20–0.22 \(in\) per turn to fully open the gate, but the limit screw moves about \( \frac{1}{8}^{\text{th}} \) that distance. In all, whole 2 ft of arm travel is shrunk into about 3 in of traveller movement. Simply, the screw goes a distance \(L\) which is each spiral thread winding around the screw \(n_{\text{starts}}\) \(\times\) the pitch \(p\) of each screw.

L=nstarts⋅p=nstartsTPIL = n_{\text{starts}} \cdot p = \frac{n_{\text{starts}}}{\text{TPI}}

In this setup, both screws turn together. The limit screw is fixed to the end of the lead screw, so after a common set of \( N\) revolutions each screw goes a total length \(s\) of:

sarm=N⋅Lleadstrav=N⋅Llimits_{\text{arm}} = N \cdot L_{\text{lead}} \qquad s_{\text{trav}} = N \cdot L_{\text{limit}}

For the full stroke the revolutions are the same,

N=24in0.21in/rev≈114 revN = \frac{24\;\text{in}}{0.21\;\text{in/rev}} \approx 114\ \text{rev}
LLim=stravN=3.6in144rev=0.025in/rev=40tpi\, L_{\text{Lim}} = \frac{s_{\text{trav}}}{N} = \frac{3.6 \, \text{in}}{144\, \text{rev}} = 0.025 \,\text{in/rev} = 40 \, \text{tpi}

So the lead screw has 8x the thread density and goes 8x shorter in length.

Fig 2 – Lead screw versus limit screw threads

The geometry of the setup can teach us a lot about how stuff works. The lead screw pushes the rod out several feet, but it pushes only about 4.5 ft from the hinge, so a short push near the pivot becomes a long sweep at the gate’s far end. Two feet becomes 25 feet: about 20 in of stroke swings a 16 ft gate through 90°, and its tip travels about 25 ft, a quarter of a 100 ft circle. That is about 15× multiplication: the actuator’s average lever arm is about 12.7 in, compared with the tip’s 192 in, so each inch of push moves the tip about 15 in.

But nothing comes for free. The trade-off is force: holding the gate against a push at its tip takes about 15 times that force at the rod, which is why the motor’s torque is multiplied first by the gears and the ACME screw. All together, the whole chain: about 840 motor turns leads to 114 screw turns leads to 24 in of arm travel which is about 25 ft at the gate tip.

The most interesting thing for me is the offset arm. Without it the lead screw would just pull on the hinge and not push out. The bigger the offset arm, the more force transfers to the tip of the gate. How big should we make this offset? The manual recommends 6 \(\text{in}\) which has enough lever arm to break the gate away from closed, while keeping the stroke inside the actuator. More offset means a longer stroke for 90°. The actuator swings through a bigger angle, and past a point it runs out of its 24 in, which is the demo’s warning.

Arm offsetLever arm at startHinge torqueForce at tip
0 in0 in0 lb·ft0 lbf (stuck)
2 in≈ 2.5 in≈ 73 lb·ft≈ 4.6 lbf
4 in≈ 5.0 in≈ 146 lb·ft≈ 9 lbf
6 in (manual)≈ 7.5 in≈ 219 lb·ft≈ 14 lbf
9 in≈ 11.4 in≈ 333 lb·ft≈ 21 lbf

The experiment below brings all this together. Move out the pivot arm to see the effect on the force.

Illustration 3 – Change the pivot arm and drive, then open the gate.

Now that we know how everything works, I actually have to fix this gate and put the washers and spur gear together.

Fig 3 – The spur gear and screws form a rigid system

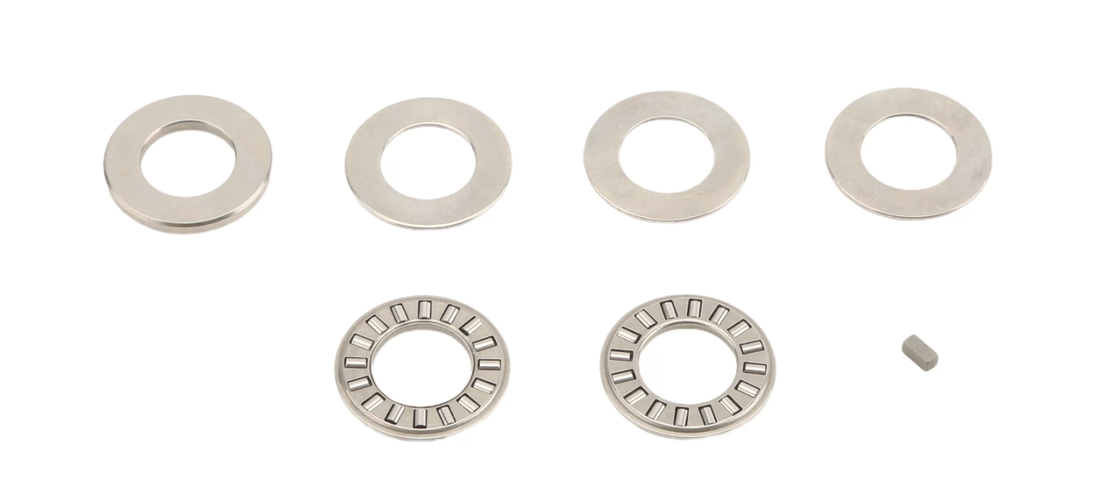
The washers in the A2087 include two needle thrust bearings. Every time the actuator pushes or pulls the gate, the gate pushes back along the lead screw, trying to shove the whole screw lengthwise out of the housing with hundreds of pounds of force. A thrust bearing takes that end-to-end load while still letting the screw spin freely. Each bearing is a sandwich. In the middle is a flat steel cage holding about twenty tiny hardened needle rollers, arranged like the spokes of a wheel. On either side is a hardened, polished race: the thin washers, plus one thicker race for the screw’s shoulder. The needles roll between the races instead of sliding, so the friction stays low even under heavy load. The races matter as much as the rollers, because they give the needles a hard, smooth track; without them, the needles would quickly dig grooves into the softer housing and gear. When a gate is making bad sounds opening and closing, it’s generally overlooked parts like this.

Fig 4 – Nice Apollo Bearing Kit (A2087)

The biggest problem for me is that little piece on the bottom right. Known a key, it’s the smallest part that does the most work: ensuring the torque is transfered from the rotating shaft to the spur gear which sits on a round, smooth section of the shaft. On its own it would just spin in place, or slip under load. To make this work, a small slot is milled lengthwise into the shaft (the keyseat), and a matching slot runs through the gear’s bore (the keyway). The square key sits half in each, bridging the two parts. All of the motor’s torque passes through that little 3/32 \(\text{in}\) bar. The Flexloc nut only stops the gear sliding off the end; it isn’t what makes the gear drive the screw.

As an engineer, I look at parts like this carefully. The key is like the derailleur hanger on your bike, strong enough to work, but weaker than the expensive parts around it. If the gate jams hard, it tends to shear the cheap key, saving a costly stripped gear or a twisted screw.

The final experiment is the diagram that matters for my current fix. Explode the assembly to see how the key ties everything together.

Illustration 4 – Explode the stack; click any part to hide it.

Hopefully this post gave you new appreciation for the beauty and thought that goes into the simple stuff around you. Today the combination of AI, youtube and Amazon/e-commerce let you understand, learn and find any part you need. These are amazing days to be a builder.

By 0 Comments

Digital Trees

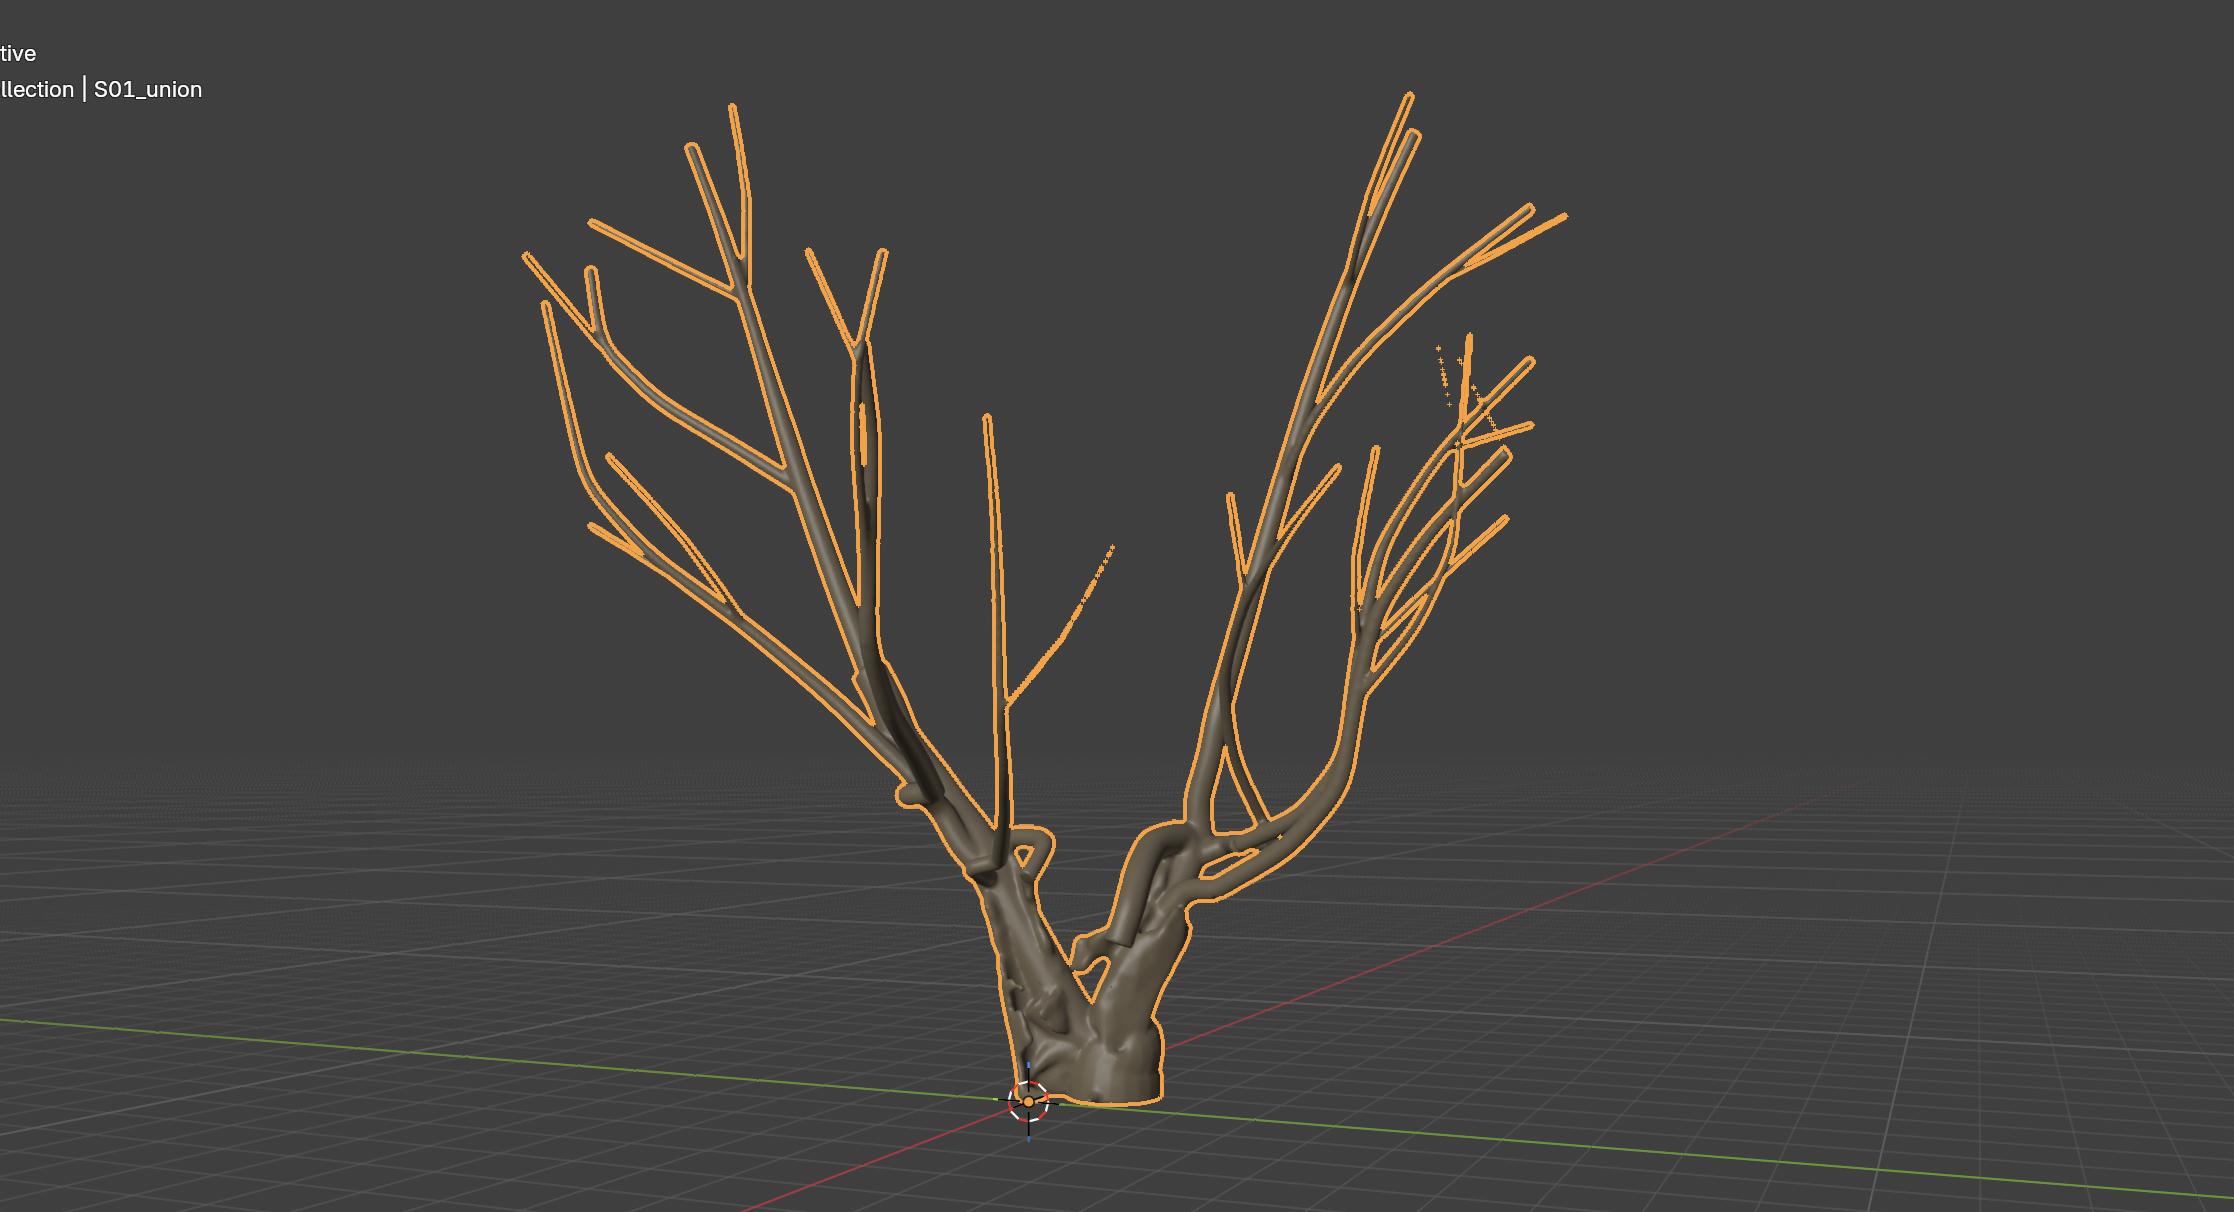
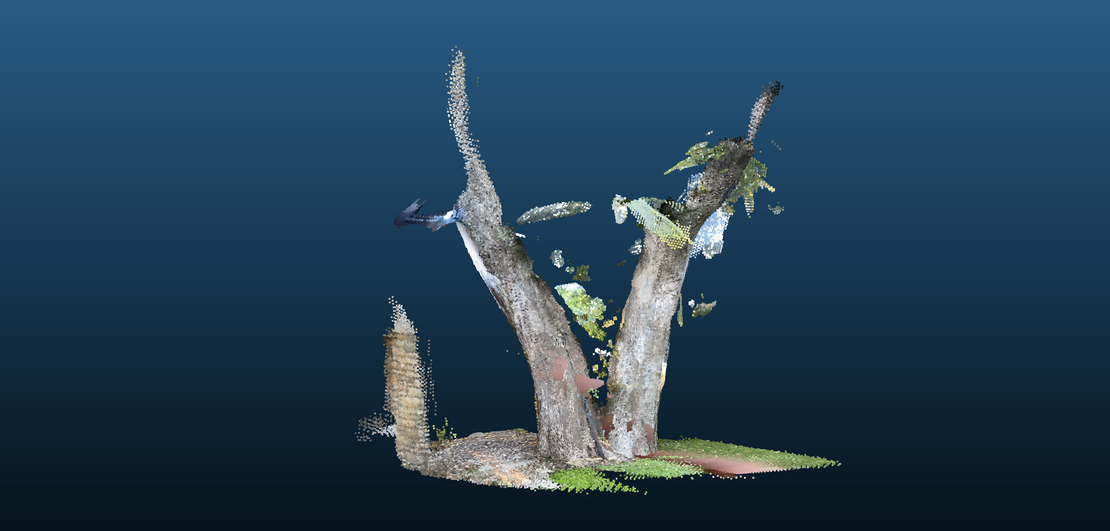
This tree is in my backyard, right behind our cabana. Go ahead, move it around and I’ll explain below how an iPhone + claude + plus some cool geometry math made this happen.

Loading tree…

I’ve always been fascinated by trees. I love how they grow in seemingly random ways, yet also obey a fixed set of rules. They form the backdrop of so many of my favorite places, always telling a story about the soil they are in and the geography around them.

In building a 3-D model of my house, I had to figure out some way to model the trees in my yard. Two things make a full model of a tree hard. First, it’s not feasible (and stupid) to get up 40 ft and do a laser scan of every branch. Second, a native scan would be huge and not useful in an architecture model.

This turns out to be a mixed-fidelity problem. You can build a mesh pretty easily, using an AI-powered tool like TRELLIS or Meshy to generate an actual mesh, resulting in hundreds of thousands of triangles without a lot of associated meaning. At the top of the tree, that may be perfectly fine. The canopy needs to be dimensionally correct and visually plausible, but the higher you go, the less it matters where each branch is located.

At the base of the tree, though, it matters a lot. A major split in the trunk, the direction of a large branch, or a limb extending over a building I’m working on can be important. The bottom of the tree needs to be real, while the top just needs to look right and be close to the correct height.

Ultimately, Revit and then rendering tools like Enscape or Trellis need the right fidelity, not maximum fidelity. And the most useful representation may not be a mesh at all. It may be a set of nodes, connections, dimensions, and rough geometry.

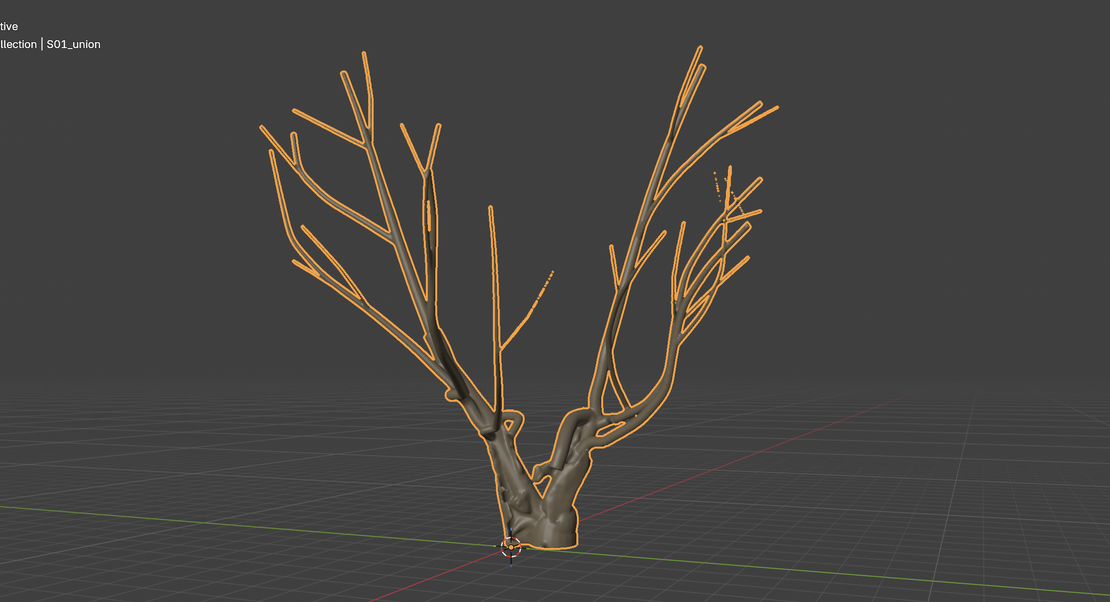
The ideal geometry is just a bunch of connected, tapered cylinders. Turns out someone has thought of this before the the internet is full of tree making programs. Enter Quantitative Structure Models, or QSMs. Instead of storing a tree as a giant triangle mesh, a QSM represents the trunk and branches as a connected graph of tapered cylinders: each segment has a start point, end point, radius, and parent-child relationship. That gives us exactly the right data structure for this problem because the measured lower part of the tree can remain geometrically accurate, while the unmeasured upper branches can be generated by Claude. This both looks accurate, but renders fast.

The iPhone and SiteScape can get me a good point cloud. No top of the tree, not even a mesh, just a bunch of dots and only observed at my height and below.

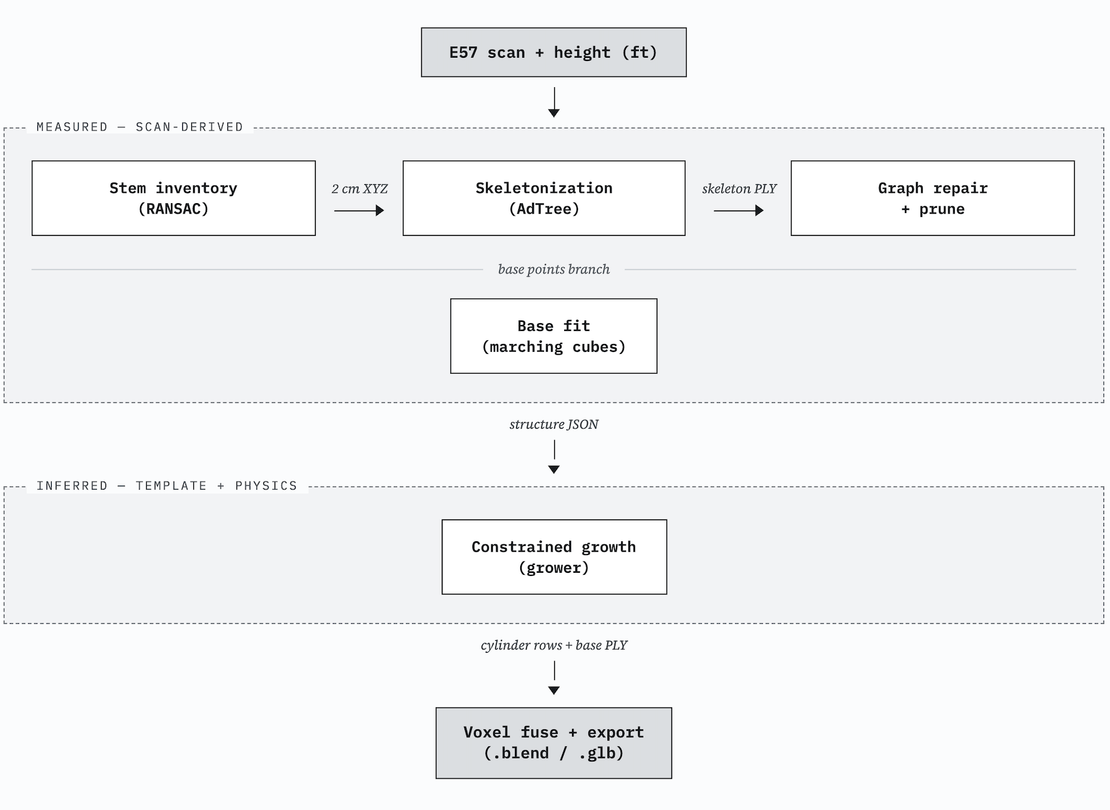
The approach that works is measurement-first, inference-last. A phone/terrestrial scan of a backyard tree only captures the lower 5–6 m, so the pipeline splits the problem: everything the scanner saw is reconstructed and locked, and everything above the scan ceiling is grown by a AI with a constraint engine rather than invented freehand.

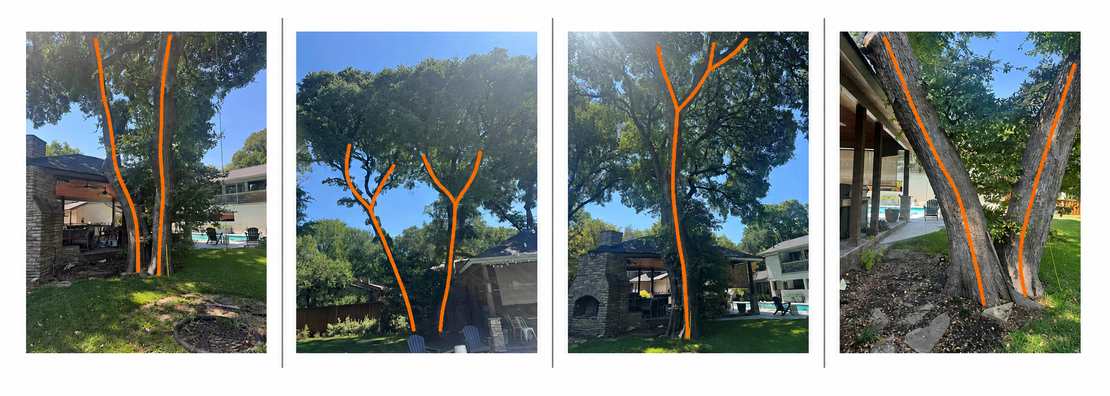
To get this right we want to give Claude all the data with an open-source tool (AdTree) that automatically reconstructs a tree’s branch skeleton and geometry from a laser-scanned point cloud. The constraints are: species (cedar elm), no central leader, sympodial forking, scaffolds arching outward), a photo-derived crown envelope, a surveyed height (46 ft by yardstick and ChatGPT), pipe-model taper at every fork, and a tapered-cantilever beam check that rejects branches that couldn’t carry their own weight. The LLM’s job is proposing and tuning those constraints and deciding which branches matter, not drawing geometry.

Forestry research tools (TreeQSM, AdTree, TreeAIBox, 3DFin) are mature at turning point clouds into cylinder models, but they reconstruct everything for biomass estimation: thousands of cylinders, collapsing radii where the scan is sparse. They are awesome, and mostly built to reconstruct a forest. My architectural models need the opposite: a few hundred faces with believable structure. So the pipeline deliberately inserts a decimation step (keep scaffolds, drop twigs) and re-derives upper radii from the trustworthy dense-zone measurements instead of the QSM’s guesses. Everything below ran locally: the reconstruction chain on a Mac (AdTree built from source, Blender via MCP for geometry), with CloudCompare’s Windows build adding TreeIso, 3DFin and TreeAIBox as a second, independent QSM to cross-check the first.

The output is pretty cool. I get a real tree that is watertight, parametric, computationally simple and structurally similar to the actual tree.

AdTree (Tech Details)

I took a look under the hood to see how AdTree works. It’s pretty cool.

AdTree converts a single-tree point set \( P=\lbrace\mathbf{p}_{i}\rbrace_{i=1}^{N}\subset\mathbb{R}^{3}\) into a rooted skeletal graph rather than reconstructing a surface directly. It first identifies points likely to lie on major branches from locally stable point density and contracts them toward branch centerlines using mean-shift. It then constructs a 3-D Delaunay proximity graph \(G_D=(V,E_D)\), assigns each edge the Euclidean cost \(\ell_{ij}=\lVert\mathbf{p}_{i}-\mathbf{p}_{j}\rVert_{2}\), and applies Dijkstra’s algorithm from the tree base to form what the paper calls a minimum spanning tree—more precisely, a rooted single-source shortest-path tree embedded in the cloud. Each skeletal vertex receives an importance \(W(v)=\sum_{e\in T_v}\ell_e\), defined as the total length of the edges in its descendant subtree, while each edge receives the mean importance of its two endpoints; low-importance basal artifacts are then pruned. Degree-two vertices are removed using a Douglas–Peucker-type test \(\alpha=d/r\leq\sigma\), where \(d\) is the vertex’s distance from the parent–child chord and \(r\) is a local edge scale, implemented using the parent-edge radius. At bifurcations, two child vertices are eligible to be merged when \(\alpha=\min\left(\ell_1\sin\theta/r_2,\ell_2\sin\theta/r_1\right)\leq\sigma\), with the replacement vertex positioned at \(\mathbf{p}_{\mathrm{new}}=(W_1\mathbf{p}_1+W_2\mathbf{p}_2)/(W_1+W_2)\). In the source implementation, merging is additionally restricted to child edges separated by an angle of approximately \(26^\circ \) or less and having lengths within a factor of two. This procedure repeatedly contracts redundant graph structure while attempting to preserve the tree’s major branching topology.

Geometry is then attached to the simplified skeleton by fitting generalized cylinders. Points near the well-sampled lower trunk are retrieved using a spatial or \(k\)-d-tree query. The trunk-cylinder parameters—an axis unit vector \(\mathbf{a}\), a point \(\mathbf{c}\) on the axis, and a radius \(r\)—are estimated by Levenberg–Marquardt minimization of the radial residual:

$$
e_i(\mathbf{a},\mathbf{c},r)= \left\lVert(\mathbf{p}_{i}-\mathbf{c})-\left[(\mathbf{p}_{i}-\mathbf{c})\cdot\mathbf{a}\right]\mathbf{a}\right\rVert_{2}-r,\qquad \min_{\mathbf{a},\mathbf{c},r}\sum_i e_i^2.
$$

AdTree then performs a second, robustified fit using \(q_i=1-\lvert e_i\rvert/\max_j\lvert e_j\rvert\). In the source implementation, \(q_i\) multiplies the residual passed to the least-squares solver, so the implemented objective is \(\sum_i(q_i e_i)^2\), reducing the influence of distant outliers. Because crown points are generally too sparse and noisy for reliable independent cylinder fitting, the remaining edge radii are inferred allometrically from subtree importance. The paper states the linear relationship \(r_e=r_t(W_e/W_t)\), where \(r_t\) and \(W_t\) belong to the fitted trunk; the source implementation instead uses \(r_e=r_t(W_e/W_t)^{1.1}\). After skeleton smoothing, generalized cylinders with varying endpoint radii are constructed along the skeletal paths and triangulated into the final OBJ mesh. Leaves are synthesized near terminal branches rather than reconstructed from LiDAR. You can think of AdTree as a graph extraction + topology-preserving simplification + partial geometric fitting + allometric completion algorithm, not a neural or direct point-to-mesh method.

I had to take this and make a hybrid technique. First, I derive all parameters diameter at breast height (DBH) is fitted by RANSAC circle regression during stem inventory; the crown envelope, branching rules, and mechanical limits come from a species template scaled to the input height; and growth seed points are computed from the measured skeleton rather than authored by hand. A single orchestrator (maketree.py) executes the nine stages as subprocesses of the repository’s stage scripts, prints a per-stage status line with wall-clock time, and halts on any gate failure. On current hardware (Apple M-series) a five-million-point scan completes in roughly twelve minutes, of which the AdTree skeletonization stage accounts for approximately nine.

The design principle is measure where the scan is dense, infer where it is not, and let physics referee the boundary. Below 3.05 m (10 ft), where point density is highest, the trunk union is meshed directly from an occupancy grid by marching cubes, no cylinder abstraction at all, because a multi-stem base is a fluted solid that swept tubes cannot represent. Above that, AdTree’s skeleton is reduced to a canonical branch graph, repaired (single-rootedness, child-to-parent attachment gap ≤ 5 mm, cloud-support pruning of spurious stubs), and extended to the surveyed height by a constrained grower whose proposals must survive a tapered-cantilever beam check and a slenderness floor \( r ≥ L/90 \) before emission. The completed skeleton is exported in TreeQSM’s cylinder interchange format, deliberately reusing the Inverse Tampere Blender add-on rather than a bespoke mesher, and the tube crown and fitted base are fused by a single voxel remesh, which yields one watertight component and makes the seam, pinch, and open-cap defect classes structurally impossible rather than individually patched.

By 0 Comments

A hometown tragedy and the need for Grace

On September 29, 2026, Caleb Flynn, a former worship pastor and American Idol contestant, was convicted of murdering his wife, Ashley, a teacher, volleyball coach, and mother of two. Ashley was shot in their Tipp City, Ohio, home in February. Prosecutors presented evidence that Caleb, who was having an affair with a fellow worship leader, staged a burglary to conceal the killing.

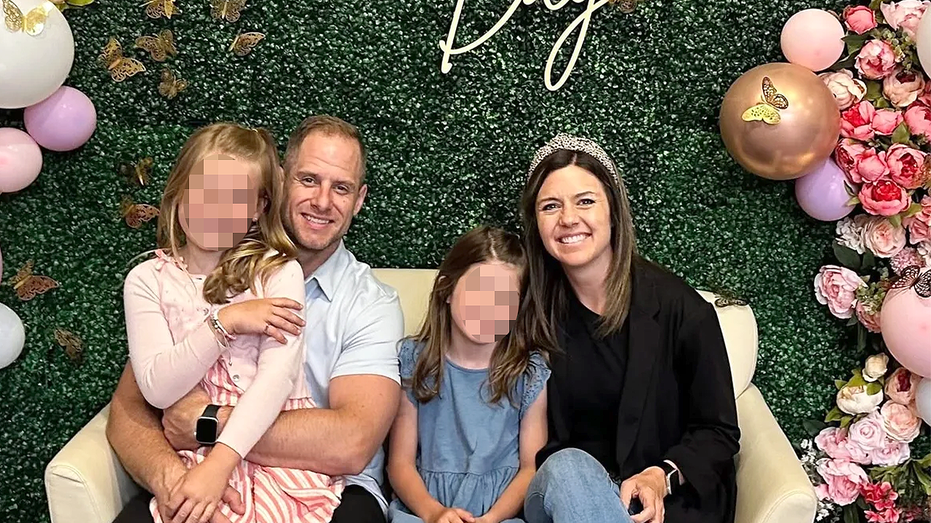
Recent Family Picture at Church

This story is sad and disorienting. It’s sad because of the destroyed dreams, the broken promises and the glaring betrayal executed under the highly produced protection of midwest evangelical Christianity. It’s disorienting because this is my small hometown.

In high school, I preached a sermon to the Christian Life Center youth group where multiple friends attended. Driving by the CLC is a staple of landing in the Dayton airport. Ashley Flynn lived and was murdered right next to my high school. She was the 4th grade teacher and volleyball coach to friend’s kids. She was friends with several folks in my family.

Christian Life Center Exterior

But it’s more than that. It’s disorienting because the villains here are relatable as they are repulsive. On the surface, Caleb Flynn is wildly different than me. I have no real musical talent and am much less rooted and known in my local hometown. Still, we are both middle aged fit guys from the same culture and faith. We are husbands, fathers and connected to the same small part of the world that is the Christian community of north Dayton Ohio. We easily could have been friends.

My theology tells me that I’m morally no better (nor worse) than Caleb Flynn.1 Any goodness in me is a gift. That said, a friend told me, “But Tim, you didn’t have an affair and kill your wife.” He is right. Faithfulness and betrayal are not morally equivalent. Any goodness in my life doesn’t make me the source of that goodness. God’s grace does more than forgive sin; it renews the heart, strengthens obedience and teaches us to love what is good. The good works we do are real, but they remain a gift. We Christians are responsible for our choices, yet dependent on Him for the strength to choose rightly.2

One of the Bible’s greatest heroes was a man after God’s own heart. God gave King David the courage and strength to slay the giant who oppressed an entire nation. And yet, “he saw a woman bathing, and the woman was very beautiful to look at” (2 Samuel 11:2). That beautiful sight led him to send for her start an illicit affair. When she became pregnant, he tried to conceal what he had done and finally arranged the death of her husband, Uriah, a loyal and honorable man. Thousands of years apart, same pattern of brokenness and pain.

Arrogance, pride, lust, power, even novelty, universally tempt all of us, even when CS Lewis already excellently summed up how sin destroys joy in the banter between two demons who describe sin as: “An ever increasing craving for an ever diminishing pleasure is the formula.”3

When we know where a path leads, why can its start still look so attractive? I find something uncomfortable in my own response to this story and the way media elevates the emotional parts of romance over commitment and duty. Alongside the disgust and sadness, I recognize the appeal of being intensely wanted, of novelty, of a secret that makes ordinary life feel suddenly electric.

Our brains are wired to imagine the thrill while escaping the cost, as though the pleasure could be separated from the people we would betray. Knowing that a desire is destructive does not necessarily make us stop wanting it. In some sense, we are even drawn towards destruction. We need grace not only to govern our actions, but to correctly order and change what we love.

But, here the consequences are right in front of us. Despite the hollywood appeal of an illicit love story, Ashley’s death confronts us with a person betrayed and a family shattered. What looks like romance when we leave out those who suffer becomes truly evil when we bring them back into view.

The start of the journey

Ashley Flynn was a woman whose profile picture consistently included her husband. Ashley knew her marriage was struggling, but she was fighting for it. In a note saved on her phone, she wrote, “We really need Jesus to intervene.”4 Later, her goals included getting on the same page with Caleb. Meanwhile, Caleb was sending his mistress messages saying he hated Ashley and wanted her dead. Her family had welcomed him into their lives and trusted him with a place in their business.

Here is a man with enumerable blessings. Nothing is more precious (and rare) in our modern world than having roots and meaning. Nothing is more sought after than to be the guy that other men want to be and who comes home to a loving family. His place in the community and christian affiliations led to success in his job selling furniture and flooring to churches. He had a beautiful wife and daughters, who by everything I can read, trusted and loved him. He had a wife fighting for their marriage until she was shot twice in the head.

What, if anything, does great blessing have to do with great sin? Ashley Flynn could still be dead from an unlucky bum who couldn’t carry a tune. We have this phrase “special place in hell” for sin that gets wrapped in special packaging, but I just can’t rev up the engine of injustice and anger for this situation. The destruction is raw in front of us as we watch this ghoul of a once alive man sit in the middle of a room while the system orchestrates the deserved destruction of his life.

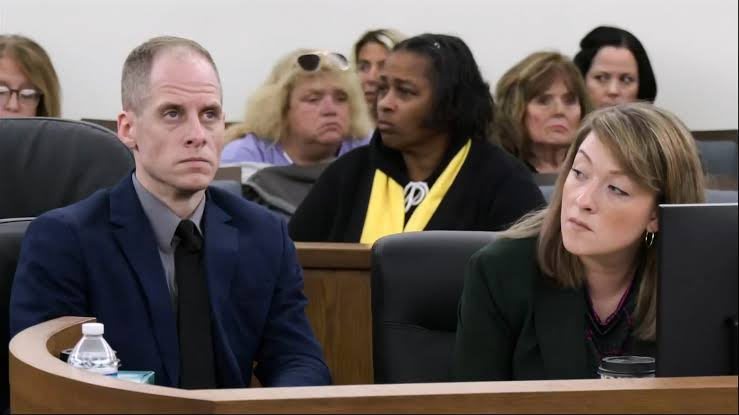
Caleb Flynn in Trial

The defendant is simultaneously both present and absent in that courtroom. Absent because he can’t live with us in the present. He is shuffled in and out while we build things and hug those we love. He sits alone with his thoughts in a cell while we focus on our hurting back or annoying driver that just isn’t getting out of our way. He appears to be only living in the regretful past and in a terrible future, helpless to do anything to change his situation.

My faith tells me that there is always hope of redemption. King David experienced incredible loss and met it with true repentance and eventually restoration. That clearly isn’t possible without confession of some sort, so this man seems stuck, locked out of the present.

What is a good man to feel about all this? Extreme sadness for the loss? Gratefulness for the embrace of my own family? Comfort in the good reward of my better choices? Glad to watch the wheels of justice turn? All the above?

I want justice, but I find no satisfaction in the ruin before me. Mostly, I feel sadness and fear: sadness for all that has been lost, and fear at what someone from my own community — and I myself — could be capable of. And I resonate with all of those questions, but I don’t know how to hold them together except by running into my Father’s arms and thanking him for sparing me and the people I love a road like this. That leaves me in love with His goodness and thankful for every breath. At some point, thankfulness merges into worship.

And that’s an odd place to end up: worship . . . the very job of this once-among-us man named Caleb Flynn. A man who once with his mistress skillfully and earnestly5 led a crowd of worshiping Christians. The picture tells us a truth: hands lifted up, the crowd was looking past that the two of them to a risen Savior who is still good and who knows what this all means. Here very fallen people have dishonored God’s name, but they (and we) cannot diminish His goodness or glory.

Flynn and Botner Lead worship together

Caleb Flynn has destroyed his marriage, his own life and deeply wounded his family and his community. God remains good. I remain thankful. Come Lord Jesus.

  1. By “no better,” I mean that we share the same fallen nature and that I have no goodness independent of God’s grace (Romans 3:9–12; 1 Corinthians 4:7). This does not mean equal guilt: Reformed theology recognizes that some sins are more grievous than others (Westminster Confession 6.2–4, 16.3; Larger Catechism 150) ↩︎
  2. This expresses the Reformed doctrine of sanctification by grace: God produces genuine goodness in us, so obedience matters, but gives us no grounds for boasting. Westminster Confession 13.1 and 16.2–3 teaches that grace renews us and empowers good works without removing our duty to obey. Canons of Dort III/IV.15–16 similarly describes undeserved grace that heals the will and produces willing obedience. ↩︎
  3. C. S. Lewis, The Screwtape Letters, Letter IX (9) ↩︎
  4. The line comes from a note recovered from Ashley Flynn’s phone and shown in court during her husband Caleb Flynn’s murder trial in Miami County, Ohio.
    Court reporters covering the Sept. 28, 2026 testimony quoted it directly. Angenette Levy of Law&Crime / Court TV posted this note from Ashley’s phone: “now I would say our marriage is struggling. Zero intimacy, respect, fondness, appreciation, nothing. We really need Jesus to intervene.” ↩︎
  5. This may need an explanation. Luther’s simul iustus et peccator means “at once righteous and a sinner”: believers are justified through Christ while still struggling with sin. I believe his earnestness could have coexisted with grave sin; sincerity does not establish saving faith or excuse the refusal to repent. ↩︎
By 2 Comments

Cyber Defense Is Losing

While at DARPA I once debated that Cybersecurity would at some point be solved. I argued that if we just built and implemented software correctly, DEFCON would be no more exciting than whatever the people who make bolts and hardware do for a convention. Boring, commoditized and expected.

Well, I’ll concede that cyber isn’t getting solved anytime soon. While AI may eventually present the ability to develop and implement secure software, right now the attacker is getting nearly all the benefits. This is because AI generated code is buggy, our world is increasing in scale and complexity, and now offense is easy while defending remains hard.

For a long time, there has been a fragile balance between offense and defense — a perfect environment to build a cyber company. Everything has been getting bigger and more digital at once: more data, more devices, more software, more dependencies. Complexity and scale make defense difficult, but new tech always rose to this challenge. This all worked as long as offense remained the domain of the skilled hacker.

Recent AI advances turn two known properties of the offense/defense game into a big problem at scale, tipping this balance. The life blood of cyber is vulnerability discovery, we learn how software can break. This information allows attackers to write exploits to take over systems, while defenders implement patches to fix the software.

First, while both are fragile, exploits are certain while patching is an exercise in hope. Once an attacker has working exploit code, it tends to work the same way every time against every still-vulnerable target. The attacker has a master key. The defender, by contrast, has to run a messy social and technical process: identify the affected systems, test the fix, schedule the outage, avoid breaking production, coordinate with vendors, and hope nothing critical was missed. You never really know how certain a patch is. The exploit (and the access it gives you) is truth. The patch is a potential improvement in security.

Second, offense needs one opening while defense needs universal coverage. A large enterprise is not defending a single castle wall. It is defending an every changing city with millions of doors: endpoints, cloud workloads, identities, APIs, SaaS integrations, vendor pathways, forgotten development environments, and software libraries nested inside software libraries. The attacker only needs one of those doors to stay open long enough to matter.

Those two facts explain more about the current cyber moment than most product categories, frameworks, or buzzwords. And both of them are radically accelerated by the long trend that mythos is putting right in front of us.

The Patch Gap

Think of a flaw in a widely used lock. The moment someone publishes a working bypass, every copy of that lock in the world shares the same weakness. The offensive advantage arrives instantly and spreads perfectly. The defensive fix does not.

That fix has to diffuse through institutions. Some teams patch in hours. Some patch in weeks. Some wait for a vendor. Some do not know they are exposed. Some know, but cannot patch without risking a more immediate outage. Some are carrying vulnerable code inside a container inside a product they do not control. The result is the same pattern every time: attacker capability jumps to near total coverage immediately, while defender coverage crawls upward over months or years and never quite reaches 100 percent. Additionally, the patch will prevent the known mechanism of the exploit, but do other vulnerabilities exist? Maybe the new patch created them.

This is the patch gap. It is where a large fraction of real-world compromise lives.

Real example: Log4Shell made the pattern visible to everyone. The vulnerability was obvious, the exploitation path was clear, and the world still spent months chasing it. Years later, defenders were still seeing exploit attempts because the tail never fully disappeared. The lesson was not just that organizations should patch faster. It was that patching is constrained by logistics, testing, ownership, incentives, and plain institutional friction. Even when everyone agrees on what should happen, it does not happen uniformly.

AI makes this worse before it makes it better. It is already helping discover vulnerabilities faster, write proof-of-concept exploits faster, and scale reconnaissance faster. That compresses the time between flaw discovery and usable offensive tradecraft. Unless defensive remediation becomes equally automated, the patch gap widens.

One vs. All

The second asymmetry is simpler and harsher. Attackers need one success. Defenders need comprehensive performance across an enormous attack surface.

There is a reason experienced defenders sound pessimistic even when they are competent. They have internalized the arithmetic. If an organization has \(n\) things that can fail, and each of them is secure with probability \(p\) on a given day, then the chance that everything is secure is \(p^n\). Once \(n\) is large enough, even very high values of \(p\) stop feeling reassuring.

That is not a slogan. It is a scaling law.

Suppose your controls are extremely good. Suppose each asset is secure 99.999 percent of the time. That sounds excellent until you apply it across millions of assets, identities, services, and dependencies. The question stops being whether a failure exists and becomes where it exists, how exposed it is, and whether the attacker finds it before you do.

This is why “we are pretty good on average” is not a comforting statement in cyber defense. Averages do not defend networks. Coverage does.

It also explains why the workforce problem is not simply a hiring problem. The surface being defended has grown much faster than the workforce available to defend it. Cloud expansion, SaaS sprawl, API dependency chains, machine identities, and AI-generated code have all increased the number of doors faster than institutions can add trained defenders. Even if every hiring pipeline worked better, the denominator is still outrunning the numerator.

Why AI Changes the Balance

AI does not create these asymmetries, but it does intensify them. The core question is “what can AI do and what permissions do we give it?” It can now exploit the software it’s given. It can (and should not) have access to all computers and the authority to quickly patch them.

On offense, AI lowers the cost of attacks that used to be too expensive to bother with. Tailored phishing, malware variation, vulnerability research, and exploitation support all become cheaper and faster. That means more attackers can attempt more operations against more targets. It also means one-off attacks against smaller or previously uninteresting targets become economically viable.

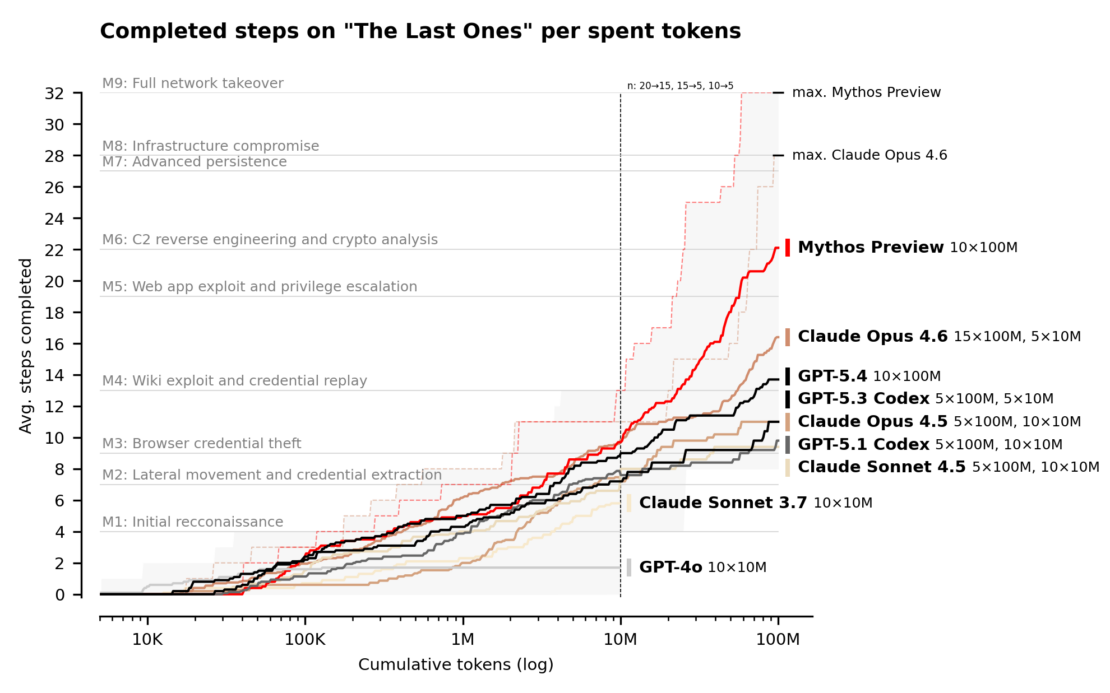
In April 2026, the UK AI Security Institute (AISI) published its evaluation of Claude Mythos Preview and reported that the model had, for the first time, completed a full 32-step corporate-network attack simulation end-to-end — from initial reconnaissance through full domain takeover — on a purpose-built cyber range. The scenario is estimated to take a human professional around twenty hours. Mythos Preview solved it start-to-finish in 3 of its 10 attempts and, across all attempts, completed an average of 22 of the 32 steps. On the expert-level individual tasks that no model could finish before April 2025, the same model succeeded 73 percent of the time. Two years earlier, frontier systems could barely complete beginner-level capture-the-flag challenges.

The chart below shows how far each frontier model gets through a multi-stage attack chain — from M1 (initial reconnaissance) up through M9 (full network takeover) — as compute budget grows. The headline is simple: Mythos is the only model that finishes the chain. Every other frontier model, including Claude Opus 4.6 and GPT-5.4, stalls somewhere in the middle — credential theft, lateral movement, infrastructure compromise — no matter how many tokens you give it. Mythos keeps going and takes over the network. There is no visible plateau in the trend, and the newest model is the one pushing autonomous exploitation from partial to end-to-end.

The Institute was careful about what this does and does not mean. The cyber ranges lacked active defenders and defensive tooling, and the model paid no penalty for noisy actions that would have lit up a real security operations center. So this is not yet evidence that AI can autonomously compromise mature enterprises. It is evidence that AI can now autonomously compromise small, weakly defended networks once access has been obtained — which happens to describe a very large fraction of the real internet. The practical implication is that the floor of “too small to be worth targeting” is rising toward the ceiling. Attacks that previously would not have cleared the economic threshold of a human operator’s time now clear the threshold of a model’s runtime.

On defense, AI can eventually help close the gap, but institutions do not adopt new defensive capabilities at machine speed. They adopt through approvals, security reviews, procurement cycles, legal caution, and operational conservatism. Attackers do not have those constraints. They do not need to justify false positives to oversight bodies or worry about accidentally disrupting their own production networks.

That is the core near-term problem: AI improves both offense and defense, but offense can usually operationalize new capability faster.

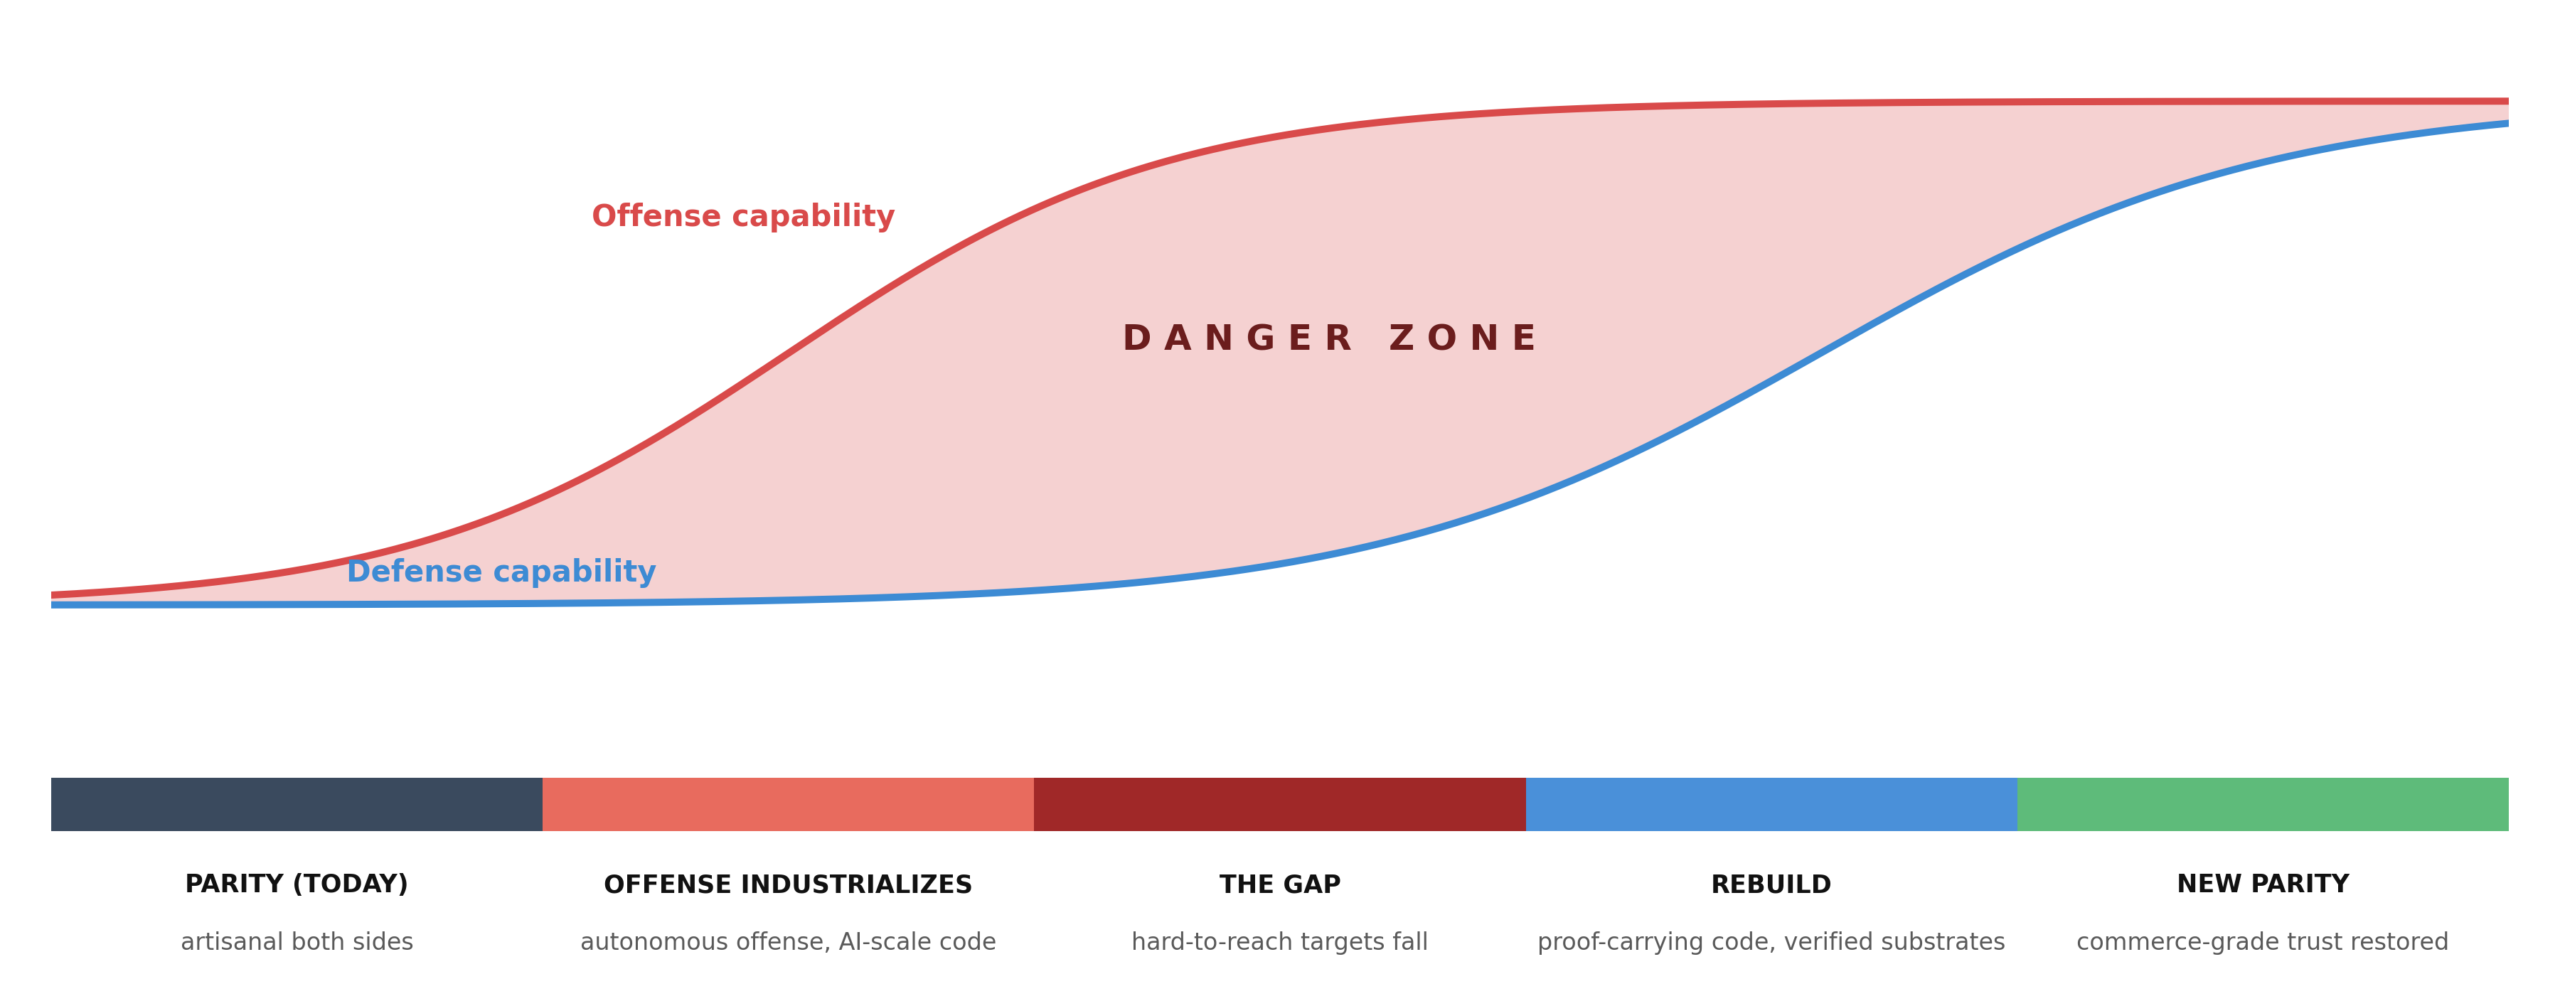
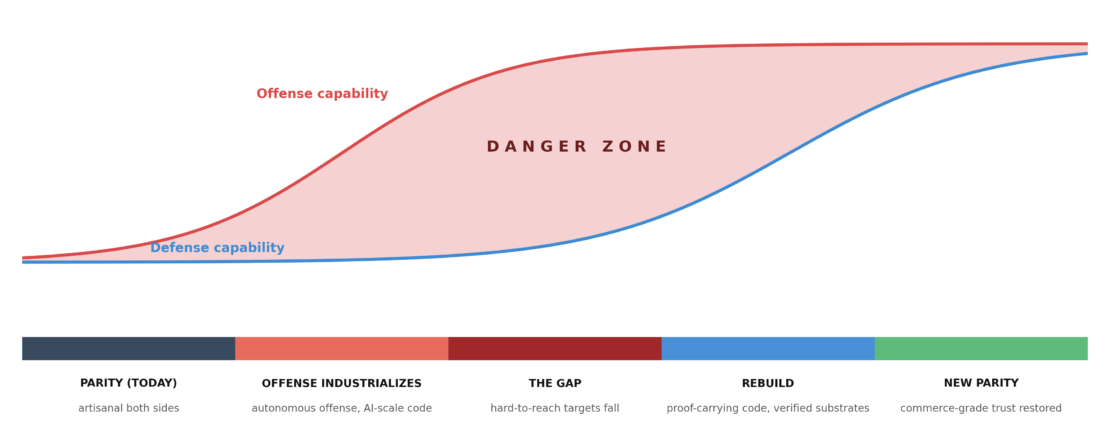
The result is a dangerous middle period — let’s call it “the period of excessive badness“. Attackers gain speed before defenders gain reliable automation. Vulnerability discovery accelerates before patching becomes autonomous. Attack campaigns become cheaper before institutions redesign authorities and workflows for machine-speed defense.

That is why the next few years are likely to be harder, not easier.

Offense spreads first. Autonomous exploitation collapses the marginal cost of finding and weaponizing a vulnerability, while AI-scale code production floods the stack with insecure software faster than humans ever shipped secure software. Defense has no symmetric productivity gain ready to deploy: formal verification, memory-safe substrates, and AI-native detection all exist as research or point tools, not as infrastructure. The result is a period of excessive badness — years in which the hard-to-reach parts of the digital world (OT, embedded systems, medical devices, legacy enterprise, firmware) pay the steepest price, because they cannot be patched on the cadence that industrialized offense now operates at. E-commerce-grade trust degrades, not uniformly, but in the places where the rebuild wave hasn’t reached.

Then comes the rebuild — paid for by the losses of the bad years, the way every prior security regime was paid for by its own catastrophe. Proof-carrying construction becomes the default for new code. Verification moves from a research artifact into the build pipeline. AI red-teaming runs continuously against every service. Hardware roots of trust, memory safety, and wide-scope AI defense get deployed as infrastructure, not features. What emerges is a new cyber parity that looks like today’s in shape — commerce works, banks work, the internet functions — but sits on a different substrate. The equilibrium holds not because attackers got worse, but because the floor got rebuilt. The policy question of this decade is not whether that end state arrives; it is how wide the gap is allowed to grow in the meantime, and which systems are sacrificed to the delay.

What This Means

The real cyber debate is usually framed in the wrong terms. People ask which vendor wins, which framework matters, or whether AI will replace analysts. Those are secondary. The first-order question is whether defenders can structurally attack the asymmetries that make offense easier — what tech is needed to correct this balance and how much damage accumulates before they do.

These are the questions I’m asking:

  • Can we compress the patch gap fast enough that working exploits do not enjoy a months-long free run?
  • Can we reduce the practical burden of defending millions of doors?
  • Can we make inevitable failures smaller, shorter, and cheaper?
  • Can we automate enough of defense that institutions are no longer asking humans to operate at a speed and scale humans were never built for?

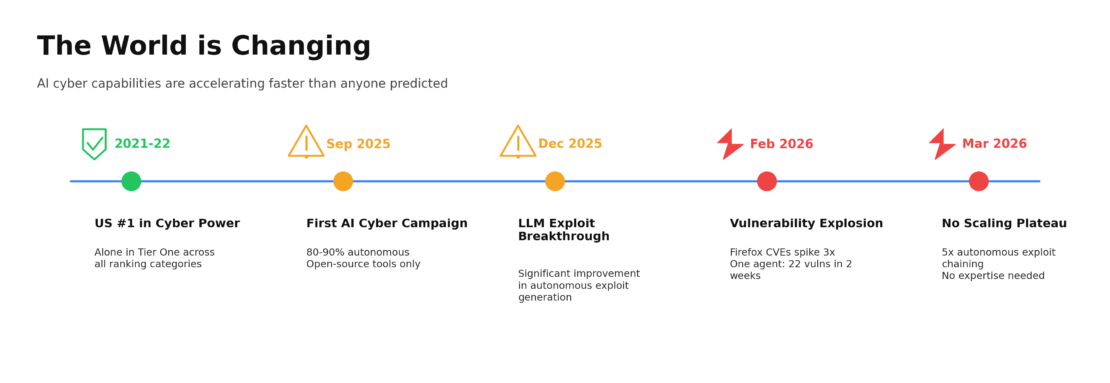
The AISI evaluation of Mythos Preview is useful mostly because it puts a clock on those questions. Two years ago, frontier models could barely complete beginner tasks. Today, one of them can solve an end-to-end corporate attack simulation that costs a skilled human most of a workweek. The next generation will not be worse at it. Every month between here and a rebuilt substrate is a month the excessive-badness period gets a little wider — and a few more of the hard-to-reach systems (OT, embedded, medical devices, legacy enterprise, firmware) get quietly written off as unsalvageable.

The end state is plausible. Proof-carrying code, memory-safe foundations, continuous AI red-teaming, wide-scope AI defense running as infrastructure — these are research artifacts and point tools today, and they become substrate in the decade ahead. What is not yet decided is how wide the gap gets on the way there, and who pays for it. That is a policy question, not a technical one.

DEFCON may never look like the bolt convention I argued it should. But the realistic win isn’t boring — it’s bounded. A period of excessive badness that ends. A rebuild that shows up in time. A new parity we actually reach, on a different substrate than the one that got us here. That, more than any single breach or product cycle, is the real story of where cyber is headed.ns from abstractions into a timer. Two years ago, frontier models could barely complete beginner tasks. Today, one of them can solve an end-to-end corporate attack simulation that costs a skilled human most of a workweek. The next generation is unlikely to be worse at it. The phases above are not a leisurely roadmap. They are the order in which defenders have to show results before the offense-defense gap becomes structurally self-reinforcing.

If the answer to those questions is no, cyber will continue to feel like a field where defenders work harder each year only to hold less ground. If the answer is yes, the next decade could mark a genuine transition from artisanal defense to industrial defense.

That, more than any single breach or product cycle, is the real story of where cyber is headed.


Sources:

By One Comment

Claude Code at Home

If you are lucky enough to have Claude code at work you get really spoiled. (I am.) You are the the bleeding edge of every update and can get an army of agents to tackle any problem. Unlike the real human world where we work a little, talk a little, get a cup of coffee and get back to work, the meter of token costs just keeps ticking.

And it’s expensive enough just to use power tools, but nothing works out of the box. You’re paying for the loop—the false starts, the “wait, let me open one more file,” the rewrite, the test, the cleanup, the second rewrite because the first rewrite wasn’t quite right. That loop is where real software gets built, and it’s also where credits vanish. It’s not that the models are overpriced in some abstract sense; it’s that the workflow is inherently iterative, and the billing model punishes iteration.

And the default model is to use the most expensive model for everything. While that’s convenient, it’s not what you should be doing at home when you have to choose between groceries or tokens.

Part of that is because these are days for being prodigal and testing a lot of things. You should be able to run things ten times in a row without feeling guilty. I want to chase a bug through a codebase, change my mind twice, and not have my brain doing mental math about whether I’m burning $8 or $80 today. I want to move fast, and I want the tool to be there the same way git is there—always available, always on, no drama.

But delegation is token-hungry by nature. The moment you let an agent do discovery—read files, skim configs, understand how tests run—you’ve entered the expensive zone. Not because the model is doing something complicated, but because the prompt becomes huge: policies, tool schemas, repo context, system instructions, plus your actual request. That’s before the model even starts thinking.

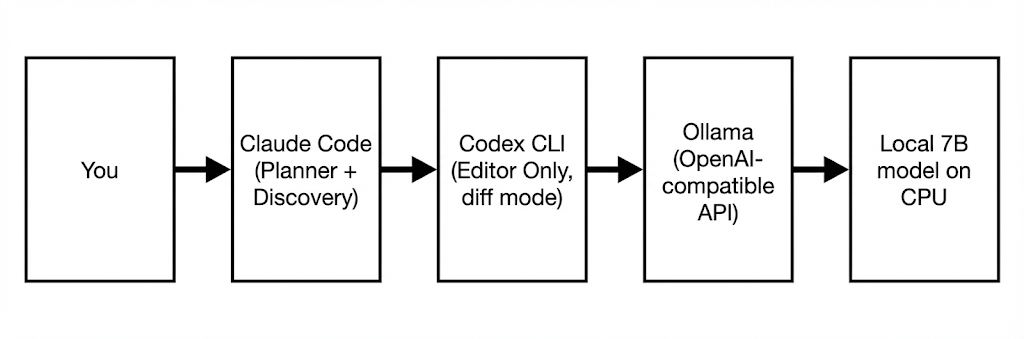
How do you actually pull this off? You let the strongest model be the boss and you assign everything else based on comparative advantage. For me that means Claude Code sits at the top as the supervisor and planner—it reads the repo, understands the architecture, and decides what needs to happen. OpenAI Codex lives one level down as the editor, taking tightly scoped instructions and producing clean diffs without wandering. And at the bottom is a locally running 7B Qwen 2.5 model through Ollama—CPU-bound, cheap, and always on—handling the boring, mechanical work. Judgment stays expensive and rare; execution becomes cheap and repeatable.

When I actually tried to do this, I found the bottleneck isn’t “can I run a model locally?” The bottleneck is “can I build a workflow that keeps my good tools while moving the expensive part out of the hot path?” Because you don’t want to give up Claude Code’s planning just to save money. You don’t want to give up Codex’s tight coding ergonomics either. You want to keep the good UI and the good behaviors, and just stop bleeding credits on every little edit.

That’s the problem statement in human terms: I want to use Claude and Codex like power tools, not like a casino meter. I want to delegate without anxiety. I want the loop back—fast iteration, lots of attempts, aggressive refactors—without that little voice saying “maybe don’t run it again.”

If you can solve that, you’re not just saving money. You’re restoring a way of working.

The good news is that the world is solving this problem. People have stopped thinking in terms of “pick one model” and started thinking in terms of “build a routing layer.” There’s been a genuine Cambrian explosion of models—open ones, semi-open ones, hosted ones—and developers are reacting the same way we always do when the ecosystem explodes: we put a gateway in front of it, normalize the interface, and swap engines behind the curtain. That’s why you see so much energy around OpenAI-compatible endpoints and proxies: you can point tools at one API shape and then decide later whether the request goes to Anthropic, OpenAI, Groq, a local Ollama box, or some hosted open model. LiteLLM is a clean example of this “gateway” pattern—one interface, lots of upstreams, plus routing/fallback ideas.

On the “hosted but cheaper” side, people are shopping for inference the way you shop for cloud compute: who can run decent models fast on specialized hardware at a lower price. Groq is the clearest “we are selling speed per dollar” play—very high token throughput and pricing that makes it attractive as a worker when you don’t need the absolute smartest model. OpenRouter is the marketplace version of the same instinct: one account, many models, and a routing/management layer so you can pick the right engine for the job (or let the router do it). They even publish guidance specifically about integrating Claude Code through their layer, which tells you how mainstream this “stick a router in front” approach has become.

Also popular are NVIDIA’s hosted endpoints, where you grab an NVIDIA API key and call models like Moonshot’s Kimi K2.5 through NVIDIA’s OpenAI-style chat/ completions interface. People mention it because it feels like cheating in the best way—GPU-backed inference, big context, modern agentic model, and the integration story is “just point your client at this base URL and use this model id.” NVIDIA’s own docs and blog posts are leaning into that exact pitch.

Meanwhile the other half of the world is going the opposite direction: “stop paying per token, I’ll run it myself.” Ollama on a workstation, LM Studio on a laptop, local quantized coding models, and a bunch of people stitching that into their editors so the ‘boring’ work has near-zero marginal cost. What’s interesting is that these two camps—cheap hosted inference and local inference—are converging on the same mental model: keep your premium model for judgment, and feed the grind to something cheaper, whether that’s a local box or a commodity inference provider. The tooling ecosystem is starting to assume you’ll do that, which is why everything is racing toward OpenAI-compatible APIs and “provider” abstractions.

What I ended up building is a split-brain workflow that feels obvious in hindsight: Claude stays in the driver’s seat as the planner and “reader,” and Codex becomes a local editor that only does the mechanical part—turning a very specific instruction into a clean diff. Under the hood, Codex isn’t talking to OpenAI at all; it’s pointed at an Ollama server running on the same machine, and Ollama is serving a small, cheap Qwen 2.5 7B model. The key design choice is that the local model never does discovery. It doesn’t roam your repo, it doesn’t decide what matters, it doesn’t try to be clever. Claude reads the codebase and decides exactly what should change; then it hands Codex a bounded edit task with the relevant file contents included, and Codex outputs a patch and stops. That’s the whole trick: you keep “judgment” expensive and rare, and you make “execution” cheap and repeatable.

To do this, install Ollama, then pull a model that’s small enough to be comfortable on CPU—Qwen 2.5 7B is a good starting point. The gotcha is that agentic tools like Codex have a surprisingly fat system prompt and tool schema, so a default 4k context model can choke in weird ways; the clean fix is to create a Codex-friendly variant with a larger context window. In Ollama that’s just a Modelfile and a new model name:

ollama pull qwen2.5:7b-instruct

cat > /tmp/Modelfile <<'EOF'
FROM qwen2.5:7b-instruct
PARAMETER num_ctx 12288
EOF

ollama create qwen2.5:7b-instruct-codex -f /tmp/Modelfile

Then you point Codex at Ollama using an OpenAI-compatible base URL, and you make sure Codex isn’t silently preferring cloud auth. Logging out of Codex cloud is the simplest way to prevent accidental spend, and then you set the config to use your local model by default:

codex logout 2>/dev/null || true

# ~/.codex/config.toml
model = "qwen2.5:7b-instruct-codex"
model_provider = "ollama"

[model_providers.ollama]
name = "Ollama"
base_url = "http://localhost:11434/v1"
wire_api = "responses"

[projects."/home/tim"]
trust_level = "untrusted"

[projects."/home/tim/code"]
trust_level = "trusted"

At that point, a single command is enough to prove you’re local:

codex exec "Reply with exactly: WORKER_READY"

And the “how to actually use it” piece is mostly discipline: Claude does discovery and planning, and when it’s time to change code it produces one tight Codex command that includes the file content inline and says “output a unified diff only, then stop.” That sounds restrictive, but it’s what makes the whole thing fast and reliable on a 7B CPU worker—and it’s what turns the stack from a token furnace into something you can iterate with all day.

Now we get to the part that actually matters: was this worth it?

Because if this whole dance saves pennies but costs minutes, then it’s clever but not practical. So I ran the numbers across comparable tasks—real edits, real delegation loops—not toy prompts.

On cost alone, delegation works. It is dramatically cheaper than running everything through Opus, and marginally cheaper than just using Sonnet directly.

Average Cost Per Task

ApproachAvg Costvs Opus
Opus 4.6$0.0779baseline
Sonnet 4.5$0.013982% cheaper
Delegated (Haiku + Codex)$0.013583% cheaper

That’s not subtle. Opus is expensive. It’s phenomenal, but it’s expensive. Sonnet is already 82% cheaper than Opus for these tasks. Delegation edges Sonnet out by a hair—83% cheaper than Opus—but the difference between Sonnet and Delegated is basically noise.

The more interesting story is speed.

Average Time Per Task

ApproachAvg Time
Sonnet 4.510.2s
Opus 4.612.2s
Delegated101.9s

Delegation is about 8.3× slower than just running Opus directly. And the bottleneck is exactly what you’d expect: Codex execution time on a local 7B CPU model. Once you leave the fast cloud inference path and move to a cheap worker, physics shows up. Thirty to one hundred twenty seconds per edit is normal.

So what does this mean in practice?

It means Sonnet 4.5 is a shockingly strong sweet spot. It’s almost as cheap as delegation—$0.0139 vs $0.0135 per task—and it’s an order of magnitude faster. If you’re optimizing purely for value per minute of your life, Sonnet direct execution is incredibly hard to beat.

Opus, meanwhile, is a premium product. At $0.0779 per task on average—5.6× more than Sonnet—it’s not what you use for mechanical edits. It’s what you use when you need the absolute best reasoning, when architecture matters, when ambiguity is high.

Now here’s the subtle part that changes the calculus: marginal cost.

When I tried to wire cloud Codex back into the stack, auth succeeded, the model resolved, and then I hit “quota exceeded.” That moment was clarifying. The architecture can’t depend on permission from a billing dashboard. If the middle layer disappears when credits run out, then it was never infrastructure — it was a subscription. So I reframed it: cloud Codex is an accelerator, not a dependency. The local worker is the default. Claude plans, the local model executes, and the system keeps running even if the cloud meter stops. If quota comes back, great — I get speed. If it doesn’t, nothing breaks. That shift — from rented capability to owned capability — is the difference between playing with AI and actually building with it.

So you end up with a very human tradeoff:

If you care about speed and you’re willing to pay $0.014 per task, Sonnet is phenomenal.

If you care about minimizing marginal cost and you can tolerate slower edits, delegation is almost free.

If you care about maximum reasoning quality, Opus is worth the premium.

The point of this architecture isn’t that delegation “wins” on every axis. It doesn’t. The point is that you now have control. You can route based on the task. You can pay for judgment and economize on repetition. You can choose whether you’re optimizing for time, money, or cognitive overhead.

And that’s the real unlock.

By One Comment

Race Report for 2025 Dallas Marathon

Dallas Marathon (Dallas, TX) 2025-12-14

I pulled my race data into a database and did a technical teardown: pacing, mile splits, and heart-rate drift, plus a practical diagnosis of what happened in the last ~2 miles and what I should train so the last 10K feels better next time. Running is a constant-improvement sport and the data reveal exactly what happened during the race and what I could do better.

Summary

Ran 3:22:21 for 26.21 miles, with a +2:22 positive split (1:40:00 / 1:42:22). For me that’s still a good marathon: controlled pacing for most of the day, normal HR drift, and then a legs-first fade late instead of a full aerobic collapse. This race was fun, with the first 24 miles just a pure joy, wanting to run faster. The last two just hurt and that is what I dig into here.

The top-line story is a modest positive split: 1:40:00 / 1:42:22. Heart rate drifted upward in the second half (normal), and the pace only really falls off in the final miles — which matches how it felt.

Location Dallas, TX
Date 2025-12-14
Start time 2025-12-14 09:00 EST
Distance 26.21 mi
Finish time (Workout.duration) 3:22:21
Moving time (Strava splits) 3:22:22
Elapsed time (Strava splits) 3:24:02
Elapsed time (stream timestamps) 3:20:57
Average pace (finish time) 7:43/mi
Avg / Max HR 151.7 / 172
Elevation gain 997 ft
Calories (Strava) 3210
Cadence (Strava) 84.9
Half split 1:40:00 / 1:42:22 (Δ 142s)
Pace steadiness (miles 2–26) 7:43/mi avg, 16.8s SD

Notes: Strava cadence is often reported as half of total steps/min for running (device-dependent). Mile splits + charts here use Strava’s per-mile moving-time splits; my earlier stream-derived splits were wrong because the imported timestamp/distance stream starts late and undercounts elapsed time.

Segment Time Avg Pace Avg HR
First half 1:40:00 7:38/mi 146.5
Second half 1:42:22 7:49/mi 156.7

Graphs

I’m mostly using these as a sanity check: if the pace line stays flat while HR drifts up, that’s normal marathon fatigue. If the pace line starts spiking up late while HR stops rising, that usually points to my legs being the limiter.

Pace by Mile (min/mi)
7:19 7:41 8:02 8:23 8:45 1 6 11 16 21 26 Mile min/mi
This uses Strava’s per-mile moving-time splits (so it matches the app’s split table).
Average HR by Mile (bpm)
164 156 148 140 131 1 6 11 16 21 26 Mile bpm
HR climbs in the second half even if pace is stable: normal marathon drift.

Mile Splits Table

My takeaway from the splits is “boringly consistent” for most of the day, with the meaningful slowdown concentrated late (miles 25–26). I’m including the full table because it’s the fastest way to see where the race actually changed.

Steadiness: miles 2–26 average pace 7:43/mi with split SD 16.8s. That’s a very controlled effort.

Mile Split Pace Cum Time Avg HR
1 7:35 7:35/mi 7:35 131.4
2 7:37 7:36/mi 15:12 143.3
3 7:39 7:39/mi 22:51 149.4
4 7:34 7:35/mi 30:25 144.0
5 7:38 7:37/mi 38:03 148.8
6 7:45 7:46/mi 45:48 149.1
7 7:44 7:44/mi 53:32 147.8
8 7:31 7:31/mi 1:01:03 148.5
9 7:35 7:35/mi 1:08:38 148.1
10 7:33 7:34/mi 1:16:11 143.2
11 7:46 7:45/mi 1:23:57 150.6
12 7:44 7:45/mi 1:31:41 148.1
13 7:29 7:29/mi 1:39:10 151.4
14 7:40 7:40/mi 1:46:50 151.9
15 7:42 7:42/mi 1:54:32 151.7
16 7:35 7:35/mi 2:02:07 153.2
17 7:37 7:36/mi 2:09:44 155.5
18 7:38 7:38/mi 2:17:22 156.3
19 8:00 8:00/mi 2:25:22 158.5
20 7:37 7:38/mi 2:32:59 163.7
21 7:29 7:28/mi 2:40:28 163.1
22 7:19 7:19/mi 2:47:47 161.4
23 7:38 7:38/mi 2:55:25 160.3
24 7:54 7:53/mi 3:03:19 157.5
25 8:17 8:17/mi 3:11:36 153.7
26 8:45 8:45/mi 3:20:21 152.7
27 (partial 0.212 mi) 2:01 9:32/mi 3:22:22 150.3

What Happened Late Race (the “legs got hard” part)

The race was controlled and just fun for a long time, but it’s a clear positive split overall, with the meaningful slowdown concentrated late. The final miles show a distinct pace drop while heart rate does not keep climbing. When my pace drops but HR doesn’t keep rising, I interpret that as a mechanical limiter: quads/calves/hip stability, stiffness, downhill damage, or just cumulative eccentric load — not a pure aerobic blow-up.

Concretely: I ran 1:40:00 / 1:42:22 (7:38/mi / 7:49/mi), and my average HR drifted from about 146.5 in the first half to about 156.7 in the second half — totally normal. The “it got really hard” part is still in the splits: mile 25 was 8:17 and mile 26 was 8:45, which are the slowest full miles.

Nutrition / Fueling Takeaways

I focused on nutrition, and the result strongly suggests it worked: a controlled marathon without a catastrophic fade is what good fueling often buys. I don’t have a precise gel-by-gel log in the data, but the next refinement is pretty standard and I can execute it intentionally next time.

My rule of thumb: start fueling earlier than I think I need to. The first hour protects the last hour. A reasonable target for a marathon effort is usually ~60–90g carbs/hour (gut tolerance dependent), and I want sodium/fluids consistent enough that I’m not inviting late cramping or that “stiff legs” feeling that shows up as pace decay.

Taper Autopsy

If I only look at the calendar, my taper looks reasonable. The DB says the last 14 days pre-race contained 35.2 miles across 14 run activities — but half of those are micro-activities (shorter than 0.75 miles or under 10 minutes). Filtering that noise out, I ran 31.5 “real” miles across 9 run-days in the final two weeks. That’s not “I stopped running.” It’s a normal reduction.

The more interesting story is intensity leakage. In the last 28 days pre-race, I logged three genuine stress runs at marathon-pace-ish or faster: D-22 was 18.14 miles at 7:45/mi (avg HR ~158), D-15 was 14.01 miles at 7:31/mi (avg HR ~154), and D-8 was 8.15 miles at 7:24/mi. Those aren’t insane workouts in isolation — but stacked inside the final three weeks, they make it harder to arrive with legs that feel springy at mile 25.

What I’d change next time: keep the routine the same, but back off the effort as race day gets close. Three weeks out is my last truly long run (18–20 miles, mostly easy, with a little marathon pace at the end only if I feel great). Two weeks out is a shorter long run (12–14) with just a small, controlled marathon‑pace segment, enough to stay sharp, not enough to beat up my legs. In the final 7–10 days, I want short reminders (strides and a few brief marathon‑pace reps), not an 8–10 mile run that quietly turns into a workout.

The point of taper isn’t to get fitter it’s to start the race rested enough to use the fitness I already built. That’s hard for me because I tend to do everything at full intensity, and I think that showed up here.

Actionable Next Steps (so the last 10K feels better)

My diagnosis is simple: my aerobic system was fine, but I didn’t have enough “fast running under fatigue” in the bank. The practical fix is to keep the long-run durability focus and add a repeatable dose of faster work (threshold and VO2-ish intervals) so marathon pace feels more like a gear I can hold late — not a gear I can hit early. That’s the missing piece when the last two miles went 8:17 and 8:45.

What my own training log says (DB-backed): in the 16 weeks before the race, I logged 399.3 miles of running (25.0 mpw average), but it was spiky (standard deviation 10.2 mpw; coefficient of variation 0.41), ranging from 8.6 miles in the lowest week to 46.9 miles in the biggest. I had 6 long runs ≥14 miles, only 3 ≥18, and just 1 ≥20 (a 23). That’s enough to run a respectable marathon, but it’s not a deep durability base for holding ~7:4x pace through mile 26, especially when some of the longest runs were already pretty demanding (e.g., 18.14 miles at 7:45/mi with avg HR ~158). My life is just too chaotic (travel every week, long hours and lots of different work from reserves to National Academies) and I needed to be more consistent to the plan versus lots of days of “let’s just get some miles in”.

What should have been different: fewer low weeks, more boring consistency. I want more weeks clustered in the 35–45 mpw range (instead of oscillating), plus one weekly threshold session and a long run that finishes at marathon pace every 2–3 weeks — while keeping the other long runs truly easy. In taper, I also want “pop without cost” (short marathon-pace touches + strides), not accidentally turning an 8–10 mile run into a sneaky hard effort. That combination is the cleanest way to make mile 25–26 feel like work instead of survival.

I’m not guessing on the “more speedwork” piece. A classic interval-training trial found that “High-aerobic intensity endurance interval training is significantly more effective than performing the same total work at either lactate threshold or at 70% HRmax, in improving VO2max” (Helgerud et al., 2007). A review on endurance determinants notes that “The speed at lactate threshold (LT) integrates all three of these variables and is the best physiological predictor of distance running performance” (Bassett & Howley, 2000). And on the durability/legs side, a strength-training review states: “Running economy is improved by performing combined endurance training with either heavy or explosive strength training” (Rønnestad & Mujika, 2014).

How I’m going to structure a typical week: two quality runs + one long run, with at least one truly easy day between stressors. If I’m stacking load (bigger mileage, more life stress, hot weather), I’ll run a two-week rotation and only do two hard sessions per week: one faster session + one long-run-specific session.

Workout 1: VO2-ish intervals (engine + form at speed): I’ll use the exact structure from that interval study because it’s simple and brutally effective: 4 × 4 minutes hard with 3 minutes easy jog recoveries (target ~90–95% HRmax by rep 2–3; pace usually around 3K–5K effort). Alternative when I want less strain: 6 × 3 minutes hard / 2 minutes easy, or 12 × 1 minute fast / 1 minute easy. Finish with 4–6 × 20s strides if my legs feel good.

Workout 2: Threshold / “comfortably hard” (raise the sustainable ceiling): this is the session I can hit almost every week without needing hero fitness. Options I like: 3 × 10 minutes at threshold with 2 minutes easy; 2 × 20 minutes at threshold with 3–5 minutes easy; or a steady 40-minute tempo if I’m in a good groove. Effort cue: strong, controlled, not gasping; I should finish thinking “I could do one more rep,” not “I’m cooked.”

Long run: specific durability (practice holding pace late): this is where I train the exact failure mode. The staple is a long run where marathon pace happens late, not early: 18–20 miles with the last 6–10 at marathon pace. If that’s too aggressive in a given week, I’ll do 3 × 4 miles at marathon pace inside a 20-miler (1 mile easy between), or a progression long run finishing the last 30–45 minutes at “steady/MP-ish.” The goal is to teach my legs to keep rhythm when they’d rather shuffle.

Strength (2×/week, short and non-negotiable): I’ll keep this boring and specific: split squats, step-downs, single-leg RDLs, calf raises (straight- and bent-knee), plus a little trunk/hip stability. Heavy-ish but clean reps, low volume, never to failure. The job is eccentric durability and stiffness, not soreness.

One constraint I’m going to respect: speedwork only helps if I absorb it. If my easy runs start drifting faster just to survive the week, I’ll cut volume before I cut quality, and I’ll keep at most two hard sessions in a 7-day window. Consistency beats a “perfect” spreadsheet week.

Overall, what a great day. I love marathon. I love the shared sacrifice, the distance, just long enough for a hard push. This time, I was a lot smarter with nutrition, getting in the miles and doing longer slow runs. Running and biking have been a consistent staple during an exceedingly chaotic time in my life and I’m super happy to have a nice race to end the season.

By One Comment

AI Agents for Autonomy Engineers

This week I attended a DARPA workshop on the future and dimensions of agentic AI and also caught up with colleagues building flight-critical autonomy. Both communities use the word “autonomy,” but they mean different things. This post distinguishes physical autonomy (embodied systems operating in physics) from agentic AI (LLM-centered software systems operating in digital environments), and maps the design loops and tooling behind each. Full disclosure: I have real hands on experience building physically autonomous systems and am just learning how AI agents work so I’m more wordy in that section and hungry for feedback from actual AI engineers.

The DoW CTO recently consolidated critical technology areas, folding “autonomy” into “AI.” That may make sense at the budget level, but it blurs an important engineering distinction: autonomous physical systems are certified, safety-bounded, closed-loop control systems operating in the real world; agentic AI systems are closed-loop, tool-using software agents operating in digital workflows. For agentic digital systems, performance is the engineer’s goal. Physical systems are constrained by and designed for safety.

Both are feedback systems. The difference is what the loop closes over: physics (sensors → actuators) versus software (APIs → tool outputs). That single difference drives everything else: safety regimes, test strategies, and what failure looks like.

Physical autonomy (embodied AI)

Physical autonomy (often called “physical AI”) is intelligence embedded in robots, drones, vehicles, and other machines with a body. These systems don’t just predict; they act—and the consequences are kinetic. That’s why high-performing autonomy is not enough: the system must be safe under uncertainty.

Conceptually, autonomy is independence of action. Philosophically that’s old; engineering makes it concrete. In physical systems, “getting it wrong” can mean a crash, injury, or property damage—so the loop is designed to be bounded, testable, and auditable.

The physical loop (perceive → plan/control → act → learn)

Perceive. Sensors (camera, LiDAR, radar, GNSS/IMU, microphones) turn the world into signals. In practice, teams build low-latency perception pipelines around ROS 2, often with GPU acceleration (e.g., NVIDIA Isaac ROS / NITROS) and video analytics stacks (e.g., NVIDIA DeepStream).

Plan + control. Near safety-critical edges, autonomy still looks modular: perception → state estimation → planning → control. Classical tools remain dominant because they’re inspectable and constraint-aware (e.g., Nav2 for navigation; MPC toolchains like acados + CasADi when explicit constraints matter). Where LLM/VLA models help most today is at the higher level (interpreting goals, proposing constraints, generating motion primitives) while lower-level controllers enforce safety.

Act. Commands become motion through actuators and real-time control. Common building blocks include ros2_control for robot hardware interfaces and PX4 for UAV inner loops. When learned policies are deployed, they’re increasingly wrapped with safety enforcement (e.g., control barrier function “shielding” such as CBF/QP safety filters).

Learn. Physical autonomy improves through data: logs, simulation, and fleet feedback loops. Teams pair real logs with simulation (e.g., Isaac Lab / Isaac Sim) and rely on robust telemetry and replay tooling (e.g., Foxglove) to debug and improve perception and planning. The hard part is that real-world learning is constrained by cost, safety, and hardware availability.

Agentic AI (digital autonomy)

Agentic AI refers to LLM-centered systems that plan and execute multi-step tasks by calling tools, observing results, and re-planning—closing the loop over software workflows rather than physical dynamics.

External definitions help ground the term. The GAO describes AI agents as systems that can operate autonomously to accomplish complex tasks and adjust plans when actions aren’t clearly defined. NVIDIA similarly emphasizes iterative planning and reasoning to solve multi-step problems. In practice, the “agent” is the whole system: model + tools + memory + guardrails + evaluation.

The agent loop (perceive → reason → act → learn)

Perceive. Agents “sense” through connectors: files, web pages, databases, and APIs. Many production stacks use RAG (retrieval-augmented generation) so the agent can look up relevant documents before answering. That typically means embeddings + a vector database (e.g., pgvector/Postgres, Pinecone, Weaviate, Milvus, Qdrant) managed through libraries like LlamaIndex or LangChain.

Reason. This is the “autonomy” part in digital form: the system turns an ambiguous goal into a sequence of checkable steps, chooses a tool for each step, and updates the plan as results arrive. The practical trick is to move planning out of improvisational chat and into something you can debug and replay.

In production, that usually means a few concrete patterns: a planner/executor split (one component proposes a plan, another executes it—often as a planner that emits a structured plan (e.g., JSON steps with success criteria) and a constrained executor that runs one step at a time, enforces policy/permissions, and can reject a bad plan and trigger re-planning), an explicit state object (often JSON) that tracks what’s known, what’s pending, and what changed, and a workflow/graph that defines allowed transitions (including branches, retries, and “ask a human” escalations). Frameworks like LangGraph, Semantic Kernel, AutoGen, and Google ADK are popular largely because they make this structure first-class.

Mechanically, there’s no special parsing logic: the plan is parsed as normal JSON and validated against a schema (and often repaired by re-prompting if it fails). The executor is then a deterministic interpreter (a state machine / graph runner) that maps each step type to an allowed handler/tool, applies guards (required fields, permissions/approvals), and only then performs side effects.

Tooling-wise, the parts that matter most are: structured outputs (JSON schema / typed arguments), validators (e.g., schema checks and business rules), and failure policies (timeouts, backoff, idempotent retries, and fallbacks to a smaller/bigger model). That’s how “reasoning” becomes reproducible behavior instead of a clever one-off response.

Act. This is where an agent stops being “a good answer” and becomes “a system that does work.” Concretely, acting usually means calling an API (create a ticket, update a CRM record), querying a database, executing code, or triggering a workflow. The enabling tech is boring-but-critical: tool definitions with strict inputs/outputs (often JSON Schema or OpenAPI-derived), adapters/connectors to your systems, and a runtime that can execute calls, capture outputs, and feed them back into the loop. Standards like MCP are emerging to describe tools/connectors consistently across ecosystems.

The hard parts show up immediately: (1) tool selection (choosing the right function among many), (2) argument filling (mapping messy intent into typed fields without inventing values), and (3) side effects (a wrong call can email the wrong person, change the wrong record, or spend money). You also have to assume hostile inputs: prompt injection, tool-output “instructions,” and data exfiltration attempts. In practice, tool selection is usually a routing problem: you maintain a tool catalog (names, descriptions, schemas, permissions, cost/latency), retrieve a small candidate set (rules, embeddings, or a dedicated “router” model), then force the model to choose from that set (function calling / constrained output) and verify the choice (allowed tool? required approvals? inputs complete?) before executing. Production stacks handle this with layered defenses: validation and business-rule checks before execution, idempotency keys and backoff for retries, timeouts and circuit breakers for flaky dependencies, least-privilege auth (scoped tokens, service accounts), sandboxing/allow-lists for sensitive actions, explicit approvals for high-impact actions, and end-to-end observability (traces/logs so you can see what tool was called, with what arguments, and what happened).

Learn. Agent systems generate traces: prompts/messages, retrieved context, tool calls + arguments, tool outputs, decisions, and outcomes—stitched together with a trace ID. In production, this typically looks like structured logs + distributed tracing (often via OpenTelemetry), with redaction/PII controls and secure storage so you can share traces with humans without leaking secrets. The payoff is that traces become an eval dataset: you can sample failures, replay runs, and measure behavior (did it pick the right tool, ask for approval, respect policies, and terminate) using tooling such as OpenAI Evals, then iterate on prompts, routers, and (sometimes) fine-tuning.

Implementation patterns (one quick map)

If you’re building agents today, you’ll usually see one of two patterns: (1) graph/workflow orchestration (explicit steps and state; e.g., LangGraph) or (2) multi-agent role orchestration (specialized agents with handoffs; e.g., CrewAI, AutoGen, Semantic Kernel). Google’s ADK, OpenAI’s Agents SDK, and similar toolkits package these patterns with connectors, observability, and evaluation hooks.

Comparing autonomy: physics vs. software loops

AspectPhysical autonomyAgentic AI
What it operates onPhysics: sensors and actuators in messy environmentsSoftware: APIs, documents, databases, and services
Loop constraintsReal-time latency, dynamics, and safety marginsTool latency, reliability, and permission boundaries
Primary failure modesUnsafe motion, collisions, degraded sensing, hardware faultsWrong tool/arguments, prompt injection, bad data, silent side effects
How you testSimulation + field testing + certification-style evidenceEvals + traces + sandboxing + staged rollout
OversightOften human-in-the-loop for safety-critical operationsOn-the-loop monitoring with guardrails + approvals for risky actions
  • The loop is the same shape, but the domain changes everything: physics forces safety-bounded control; software forces permissions and security.
  • “Autonomy” isn’t a vibe: in both worlds it’s engineered feedback, measurable behavior, and an evidence trail.
  • Both converge on systems engineering: interfaces, observability, evaluation, and failure handling matter as much as model quality.

Where they merge (the payoff)

The most interesting systems blend the two: digital agents plan, coordinate, and monitor; embodied systems execute in the real world under strict safety constraints. You can already see this pattern in:

  • Robotics operations: agents triage logs, run diagnostics, and propose recovery actions while controllers enforce safety.
  • Warehouses and factories: agents schedule work and allocate resources; robots handle motion and manipulation.
  • Multi-robot coordination: agent-like planners coordinate tasks; low-level autonomy keeps platforms stable and safe.

Conclusion

Physical autonomy and agentic AI are two different kinds of independence: one closes the loop over physics, the other over software. Treating them as the same “AI” category hides the real engineering work: safety cases and control in the physical world; security, permissions, and eval-driven reliability in the digital world. The future is hybrid systems—but the way you build trust in them still depends on what the loop closes over.

By 0 Comments